
Meituan Open-Sources LongCat-Next: A Native Multimodal Model Integrating Vision and Voice for Physical World AI
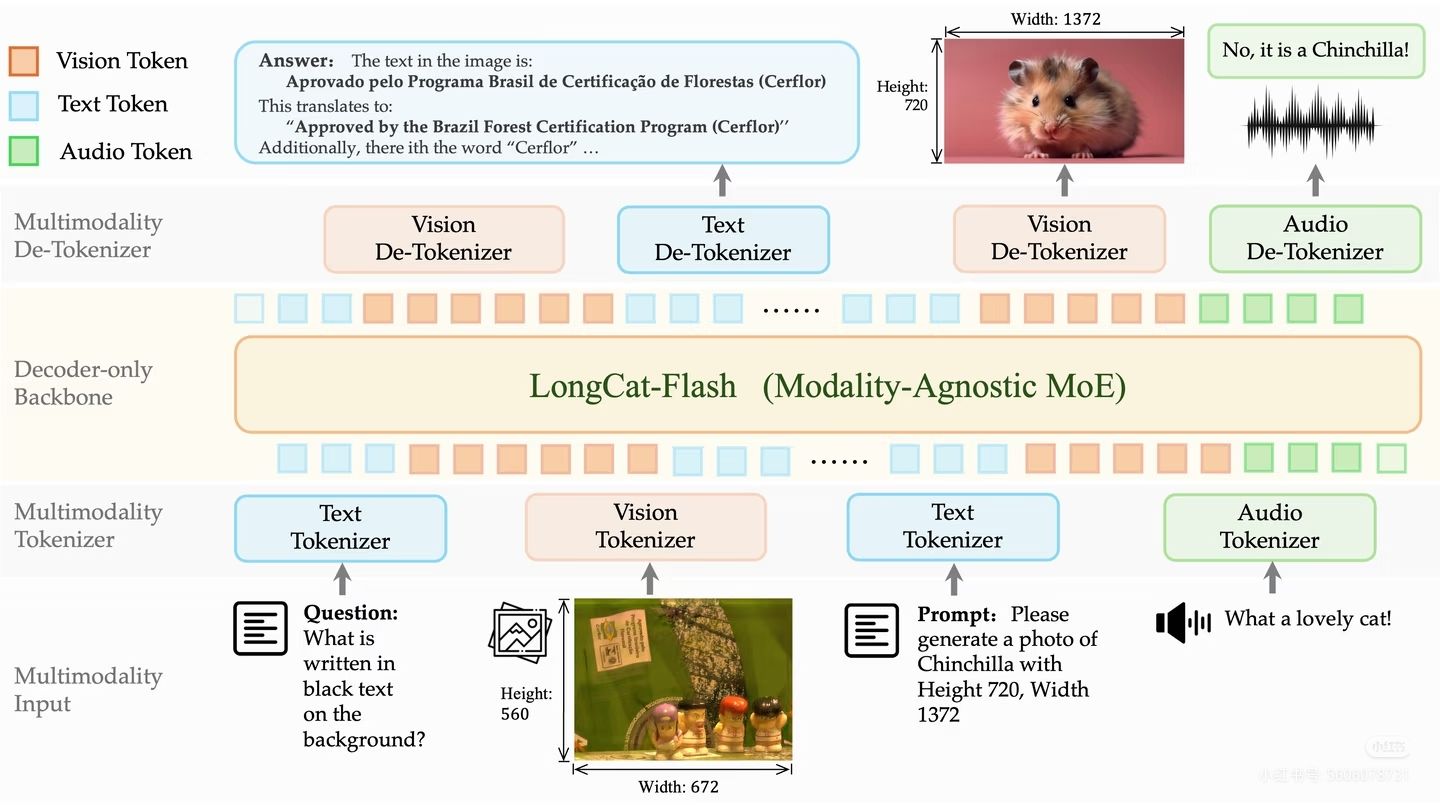
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and voice as "native languages" rather than secondary inputs, the model aims to enhance an AI's ability to perceive, understand, and interact with real-world environments. Alongside the model, Meituan has also open-sourced its discrete tokenizer, providing developers with the essential tools to build AI systems capable of acting within physical spaces. This move represents a significant step in Meituan's exploration of embodied AI and the integration of multiple sensory modalities into a single, cohesive framework.
Key Takeaways
- Native Multimodal Integration: LongCat-Next treats vision and voice as core, native components of the AI's processing capabilities.
- Open-Source Release: Meituan has open-sourced both the LongCat-Next model and its associated discrete tokenizer to the global developer community.
- Focus on the Physical World: The project is a dedicated exploration into creating AI that can perceive, understand, and act within real-world physical environments.
- Developer Empowerment: The release is intended to provide a foundation for developers to build sophisticated AI applications that interact with the tangible world.
In-Depth Analysis
Bridging the Gap to the Physical World
Meituan's release of LongCat-Next marks a strategic pivot toward what the technical team describes as "Physical World AI." Traditional AI models have largely been confined to digital environments, processing text or static images in isolation. LongCat-Next, however, is positioned as an exploration into how AI can transcend these digital boundaries. The core objective is to move beyond simple data processing and toward a system that can truly perceive and act within the physical realm. By focusing on the "physical world," Meituan is addressing the need for AI that can navigate, interact with, and understand the complexities of real-life surroundings, which is a critical requirement for applications ranging from robotics to automated services.
Vision and Voice as Native Languages
The title of the release, "When Vision and Voice Become AI's Mother Tongue," highlights the "native" nature of the LongCat-Next architecture. In many previous multimodal systems, non-textual data like audio or video were often converted or adapted to fit a text-centric model. LongCat-Next departs from this by treating vision and voice as primary modalities. This native integration suggests a more seamless and intuitive way for the model to process sensory information. By utilizing a discrete tokenizer specifically designed for these modalities, the model can interpret visual and auditory signals with the same level of fundamental understanding as it would with text, potentially leading to more accurate and responsive interactions in real-time environments.
The Strategic Value of Open-Sourcing
By open-sourcing the LongCat-Next model and its discrete tokenizer, Meituan is contributing significant intellectual property to the broader AI research community. This move is not merely a technical release but a call for collaboration. The technical team expressed a specific hope that developers would use these tools to build AI that can "perceive, understand, and act." Open-sourcing the discrete tokenizer is particularly noteworthy, as tokenization is a foundational step in how models interpret raw data. Providing these core components allows developers to look under the hood of Meituan's multimodal approach and adapt it for a wide variety of specialized use cases in the physical world, effectively accelerating the development of embodied AI.
Industry Impact
The release of LongCat-Next has several implications for the AI industry:
- Acceleration of Embodied AI: By focusing on physical world interaction, Meituan is pushing the industry toward embodied AI, where intelligence is paired with physical presence and action.
- Standardization of Multimodal Tools: Open-sourcing a discrete tokenizer for vision and voice provides a potential standard or reference point for other researchers working on native multimodal architectures.
- Lowering Barriers to Entry: Developers who previously lacked the resources to build native multimodal models from scratch can now leverage Meituan's foundational work to create complex, real-world AI applications.
- Shift in AI Training Paradigms: The emphasis on "native" vision and voice signals a shift away from text-heavy models toward more balanced, multi-sensory intelligence systems.
Frequently Asked Questions
Question: What makes LongCat-Next different from traditional AI models?
Answer: LongCat-Next is a native multimodal model, meaning it is designed to process vision and voice as primary "mother tongues" rather than secondary inputs. It is specifically built to help AI perceive and act within the physical world.
Question: What specific components has Meituan open-sourced?
Answer: Meituan has open-sourced the LongCat-Next model itself along with its discrete tokenizer, which is used to process visual and auditory data.
Question: Why is the "physical world" focus important for this model?
Answer: The focus on the physical world indicates that the model is designed for more than just digital tasks; it is intended to enable AI to understand and interact with real-life environments, which is essential for the future of robotics and autonomous systems.