
Managing AI Coding with Agent Evaluation Logic: Insights from a 310,000-Line Code Refactoring Practice
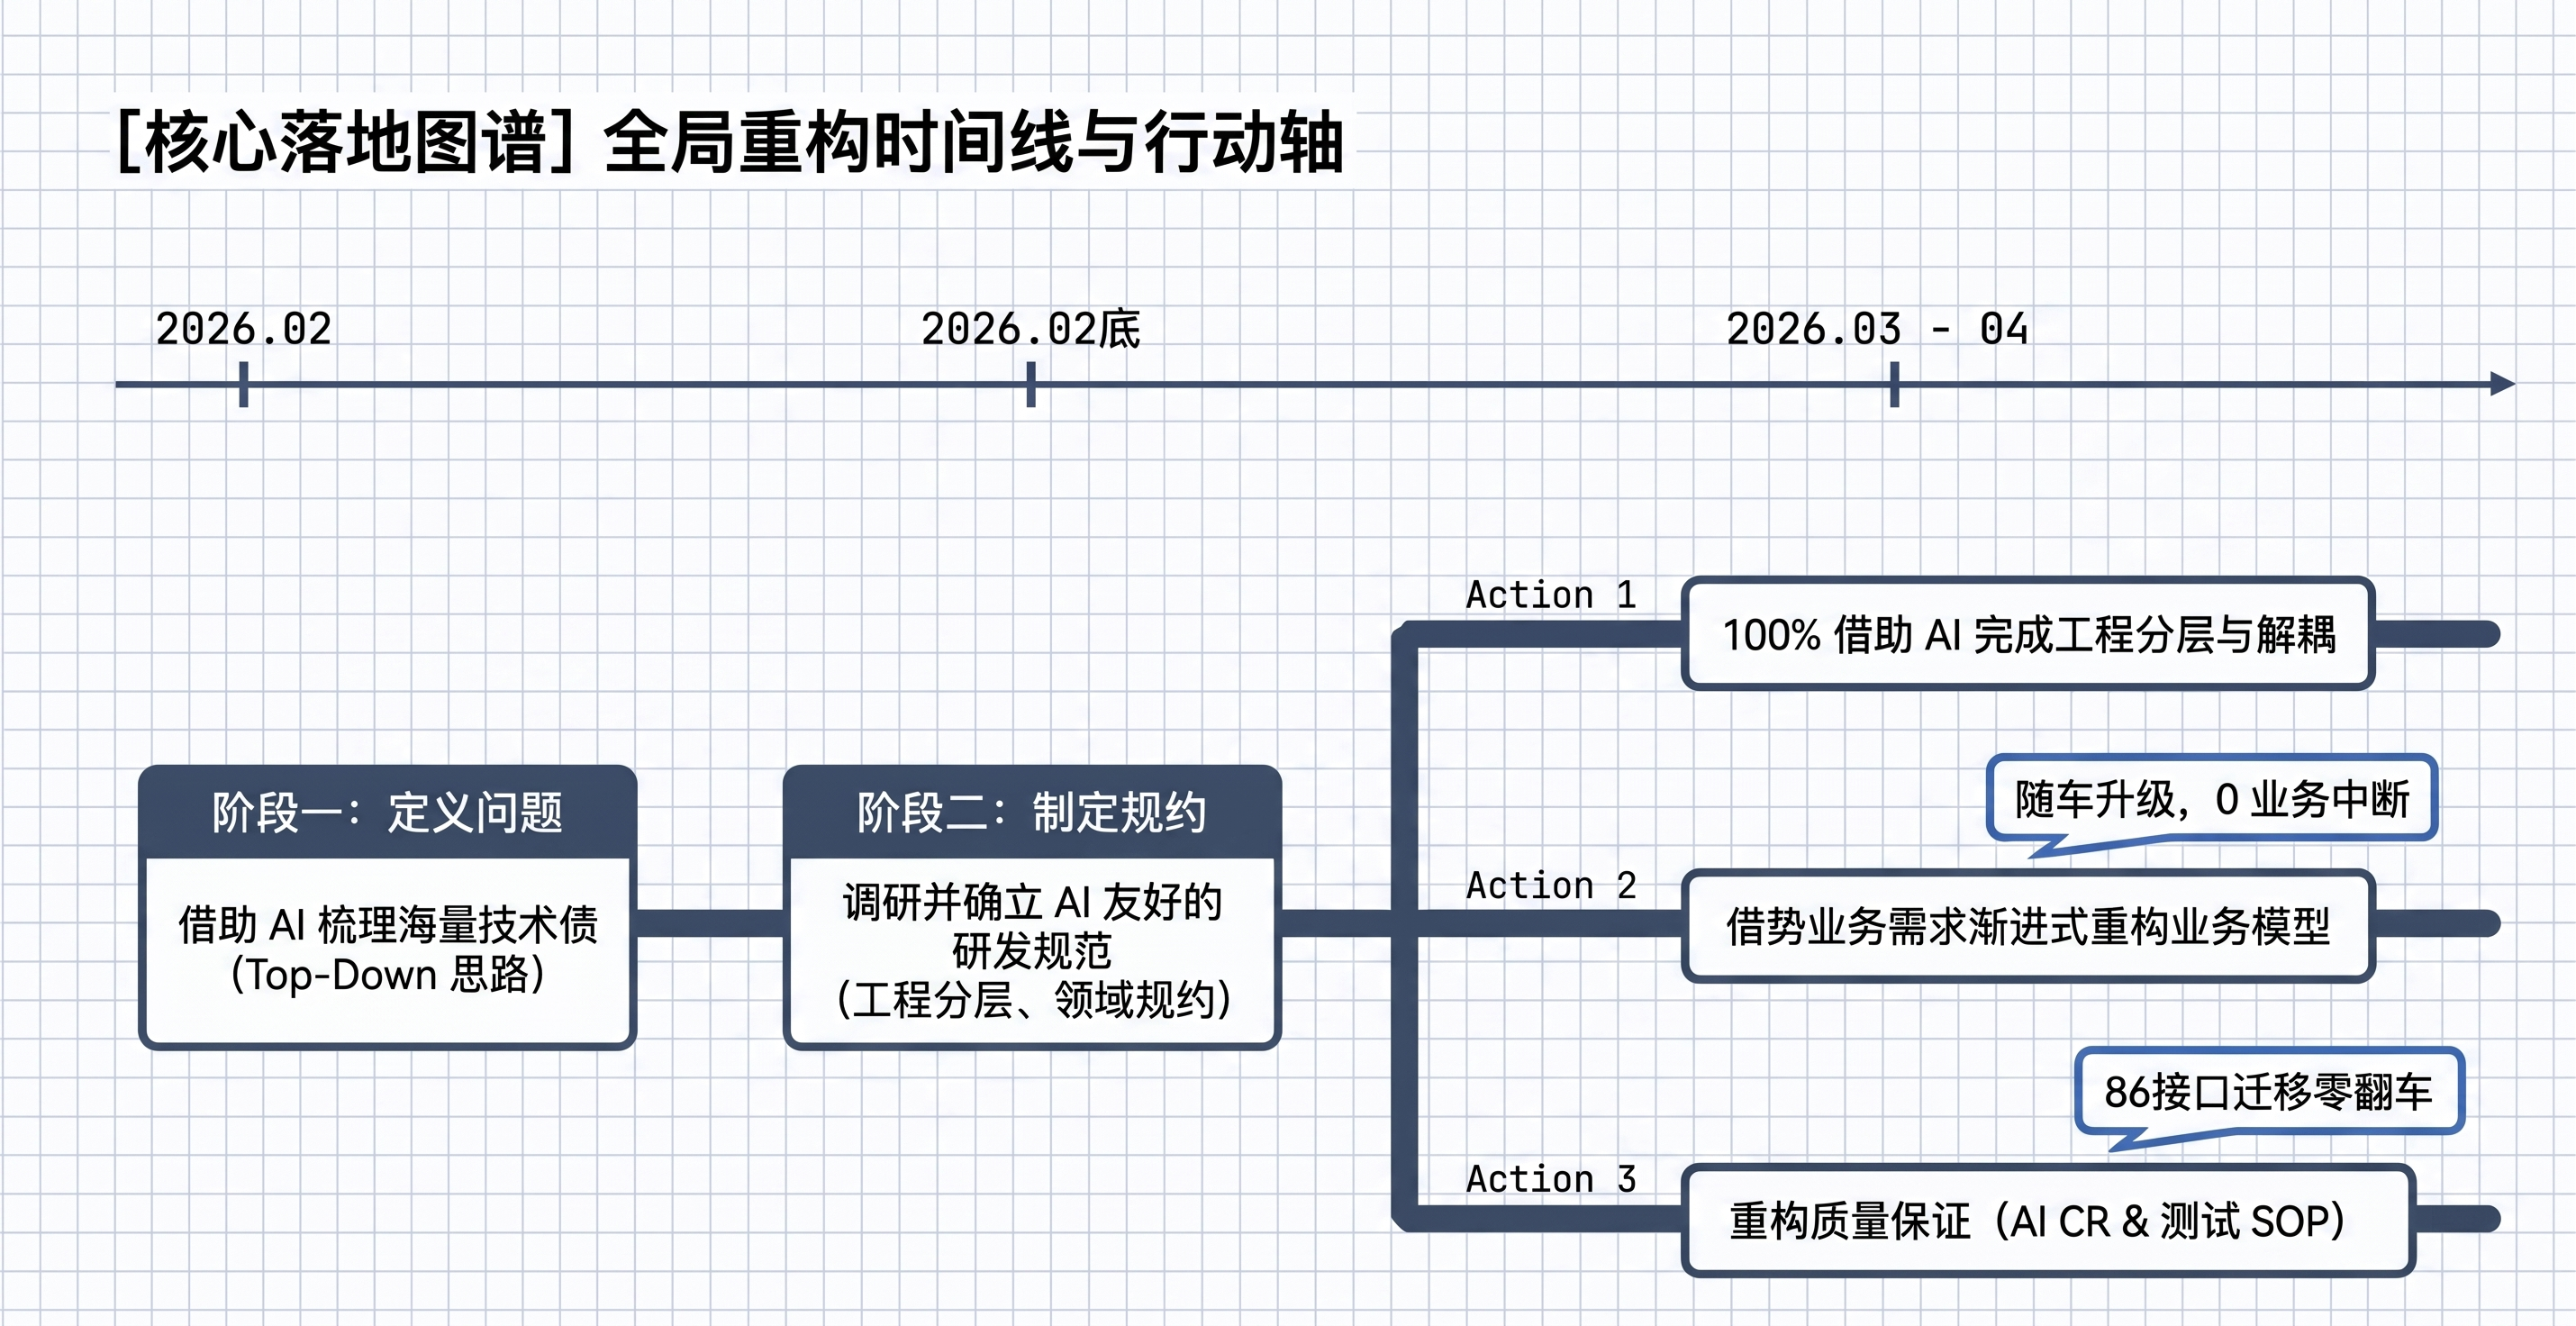
As AI-generated code begins to comprise over 90% of modern systems, the technical challenge shifts from speed to governance. Meituan's technical team has shared a comprehensive framework for managing AI coding based on their experience refactoring 310,000 lines of code. The core of their approach involves using an 'Agent evaluation' mindset to prevent AI from amplifying system chaos. By implementing technical debt sorting, rule construction, standardized operating procedures (SOPs), and a Pre-PR mechanism, the team successfully transitioned large-scale refactoring from a high-cost, specialized project into a sustainable, daily iterative process. This shift emphasizes that the ultimate trajectory of a system is determined by the constraints placed on AI rather than the speed of code generation.
Key Takeaways
- AI Scale vs. Chaos: When over 90% of code is generated by AI, the lack of unified standards can lead to a massive amplification of system chaos and technical debt.
- Agent Evaluation Mindset: Managing AI coding requires a shift toward an 'Agent evaluation' logic, focusing on constraints and quality control rather than just output volume.
- Four-Pillar Framework: Successful large-scale refactoring (310,000 lines) was achieved through technical debt sorting, rule construction, Refactoring SOPs, and a Pre-PR mechanism.
- Sustainable Iteration: The goal of these mechanisms is to transform refactoring from a high-cost, one-time 'special project' into a continuous, daily development activity.
In-Depth Analysis
The Challenge of AI-Generated Code at Scale
In the current landscape of software development, the efficiency of code generation has reached a tipping point where more than 90% of a system's codebase can be produced by AI. However, the Meituan technical team identifies a critical paradox: while AI writes code faster than humans, it does not inherently understand the long-term architectural health of a system. Without a unified set of specifications and constraints, AI tools tend to amplify existing chaos, leading to a rapid accumulation of technical debt. The primary bottleneck in modern software engineering is no longer the speed of writing code, but the ability to govern and constrain the AI to ensure the system remains maintainable and robust.
The Agent Evaluation Framework for Refactoring
To address the complexities of a 310,000-line code refactoring project, the team adopted an 'Agent evaluation' logic. This approach treats the AI as an autonomous agent that must be managed through rigorous evaluation and structured feedback loops. The first step in this process is the systematic sorting of technical debt, identifying where the AI-generated or legacy code deviates from desired standards.
Following the identification of debt, the team focused on 'Rule Construction.' By establishing clear, machine-readable rules, the AI is provided with the necessary boundaries to operate effectively. This ensures that the AI's output aligns with the specific architectural requirements of the project, preventing the 'hallucination' of coding patterns that might lead to future failures. This methodology shifts the focus from manual code reviews to the creation of a robust environment where the AI is self-correcting based on predefined constraints.
Operationalizing Refactoring: SOPs and Pre-PR Mechanisms
One of the most significant hurdles in large-scale refactoring is the cost and disruption associated with 'special projects.' Meituan’s practice demonstrates that by integrating a Refactoring Standard Operating Procedure (SOP) and a Pre-PR (Pull Request) mechanism, refactoring can become a seamless part of the daily development cycle.
The Pre-PR mechanism acts as a gatekeeper, evaluating AI-generated changes before they are even submitted for human review. This ensures that only code meeting the established rules and standards progresses through the pipeline. By standardizing these actions, the team successfully moved away from high-cost, periodic refactoring efforts toward a model of continuous improvement. This ensures that as the codebase grows through AI assistance, its quality is maintained iteratively with every code change.
Industry Impact
Meituan's approach signals a significant shift in the AI industry's relationship with automated coding. As AI agents become the primary authors of software, the role of the human developer is evolving into that of a 'system architect' and 'rule setter.' The significance of this practice lies in its scalability; by treating AI management as an evaluation problem, organizations can handle massive codebases that would be impossible to refactor manually. This sets a precedent for the industry to prioritize AI governance and automated quality assurance mechanisms, ensuring that the speed of AI development does not come at the expense of system integrity. The transition of refactoring from a 'special event' to a 'daily action' represents a new maturity level in AI-assisted software engineering (AISE).
Frequently Asked Questions
Question: Why is AI-generated code considered a potential source of 'chaos'?
AI-generated code can lead to chaos because AI models often lack the context of a specific project's long-term architecture or unified coding standards. Without strict constraints, AI may produce inconsistent patterns or ignore technical debt, which, when scaled across hundreds of thousands of lines of code, results in a system that is difficult to manage and maintain.
Question: What is the benefit of a Pre-PR mechanism in AI coding?
A Pre-PR mechanism serves as an automated quality gate that evaluates code against established rules before it reaches the human review stage. This reduces the burden on human developers, ensures consistency in the codebase, and allows for the early detection of issues, making the refactoring process a continuous part of the development iteration rather than a separate, costly task.
Question: How does 'Agent evaluation' logic differ from traditional code review?
Traditional code review often focuses on human-to-human feedback on specific logic. 'Agent evaluation' logic, in the context of AI coding, focuses on building the infrastructure—such as rules, SOPs, and automated checks—that governs how an AI agent generates and refactors code. It treats the AI as a scalable resource that requires systematic constraints to ensure its output meets high-level system requirements.
