
Meituan Releases LongCat-Next: A Native Multimodal Model Designed for Physical World AI Perception
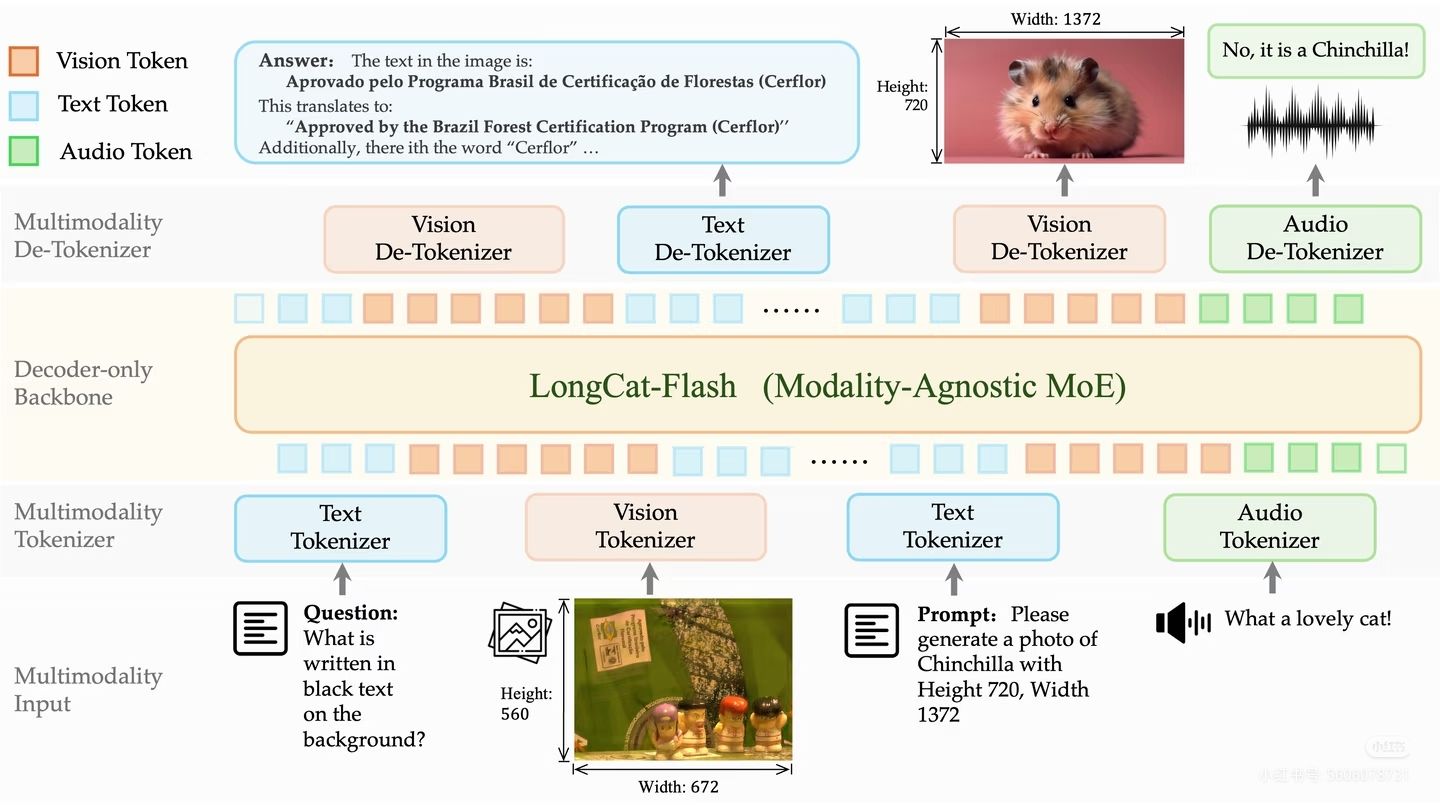
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal model that marks a significant step toward AI capable of interacting with the physical world. By treating vision and speech as "native languages" (mother tongues) rather than secondary inputs, LongCat-Next aims to bridge the gap between digital intelligence and real-world perception. Alongside the model, Meituan has open-sourced its discrete tokenizer, providing developers with the core tools necessary to build AI systems that can perceive, understand, and act within physical environments. This move highlights Meituan's commitment to open-source collaboration and its strategic focus on embodied AI and multimodal integration.
Key Takeaways
- Native Multimodal Integration: LongCat-Next treats vision and speech as "mother tongues," enabling more seamless perception of the physical world.
- Open-Source Contribution: Meituan has open-sourced both the LongCat-Next model and its core discrete tokenizer for the developer community.
- Physical World Focus: The model is specifically designed as an exploration into AI that can perceive, understand, and act upon the real world.
- Developer Empowerment: The release aims to provide a foundation for developers to build advanced AI applications that interact with physical environments.
In-Depth Analysis
The Shift Toward Native Multimodality
The introduction of LongCat-Next by Meituan represents a strategic shift in how AI models handle diverse data types. By describing vision and speech as the "mother tongues" of the model, Meituan emphasizes a native multimodal architecture. Unlike traditional AI systems that may rely on separate modules or adapters to translate visual and auditory signals into a format the core model can understand, a native multimodal approach suggests that these capabilities are integrated into the model's fundamental structure from the beginning. This design philosophy is intended to allow the AI to process environmental stimuli more naturally and efficiently, mirroring the way biological entities interact with their surroundings.
This "native" approach is critical for the development of AI that operates in the physical world. When vision and speech are integrated at the core, the model can potentially achieve a higher level of contextual awareness. For Meituan, a company deeply embedded in physical services—ranging from food delivery to local commerce—the ability for an AI to "perceive and understand" the real world is not just a theoretical exercise but a foundational requirement for future automation and service optimization.
Open-Sourcing the Discrete Tokenizer and Model Core
A pivotal aspect of the LongCat-Next announcement is the decision to open-source the model alongside its discrete tokenizer. In the context of multimodal AI, a tokenizer is the component responsible for breaking down complex data—such as images or audio waves—into discrete units that the neural network can process. By releasing the discrete tokenizer, Meituan is providing the community with the specific "lens" through which LongCat-Next views the world.
This move is designed to foster a collaborative ecosystem. Meituan's technical team explicitly stated their hope that developers will use these tools to build AI that can "act upon the real world." By lowering the barrier to entry for high-quality multimodal perception, Meituan is positioning LongCat-Next as a potential standard or foundational building block for other researchers and companies. This open-source strategy suggests that Meituan views the challenge of "Physical World AI" as a collective industry goal rather than a proprietary secret, acknowledging that the complexity of real-world interaction requires broad-based innovation.
Industry Impact
The release of LongCat-Next has significant implications for the AI industry, particularly in the fields of robotics, autonomous systems, and embodied intelligence. By focusing on the "physical world," Meituan is moving the conversation beyond Large Language Models (LLMs) that exist primarily in text-based digital environments.
- Advancement of Embodied AI: The focus on perception and action suggests that LongCat-Next is a step toward more capable embodied AI. This could accelerate the development of robots and automated systems that need to navigate and interact with human environments.
- Standardization of Multimodal Tools: By open-sourcing a discrete tokenizer specifically tuned for native multimodality, Meituan may influence how other developers approach the integration of vision and speech, potentially leading to more standardized methods for multimodal data processing.
- Bridging Digital and Physical Realms: The emphasis on "perceiving and acting" highlights a growing industry trend where AI is no longer just a tool for information retrieval, but an active participant in physical logistics and services.
Frequently Asked Questions
Question: What makes LongCat-Next different from traditional AI models?
LongCat-Next is a native multimodal model, meaning it is designed to treat vision and speech as its primary languages ("mother tongues") rather than secondary inputs. This allows for a more integrated and natural perception of the physical world compared to models that use external adapters for different data types.
Question: What specific components has Meituan open-sourced?
Meituan has open-sourced the core LongCat-Next model and its discrete tokenizer. These components represent the heart of the research team's approach to multimodal perception and are now available for developers to use as a foundation for their own projects.
Question: What is the primary goal of the LongCat-Next project?
The primary goal is to explore the path toward "Physical World AI." Meituan aims to create and share tools that enable AI to not only understand digital data but to perceive, comprehend, and take action within the real, physical environment.