
Meituan Open Sources LongCat-Next: Advancing Native Multimodal AI for Physical World Interaction
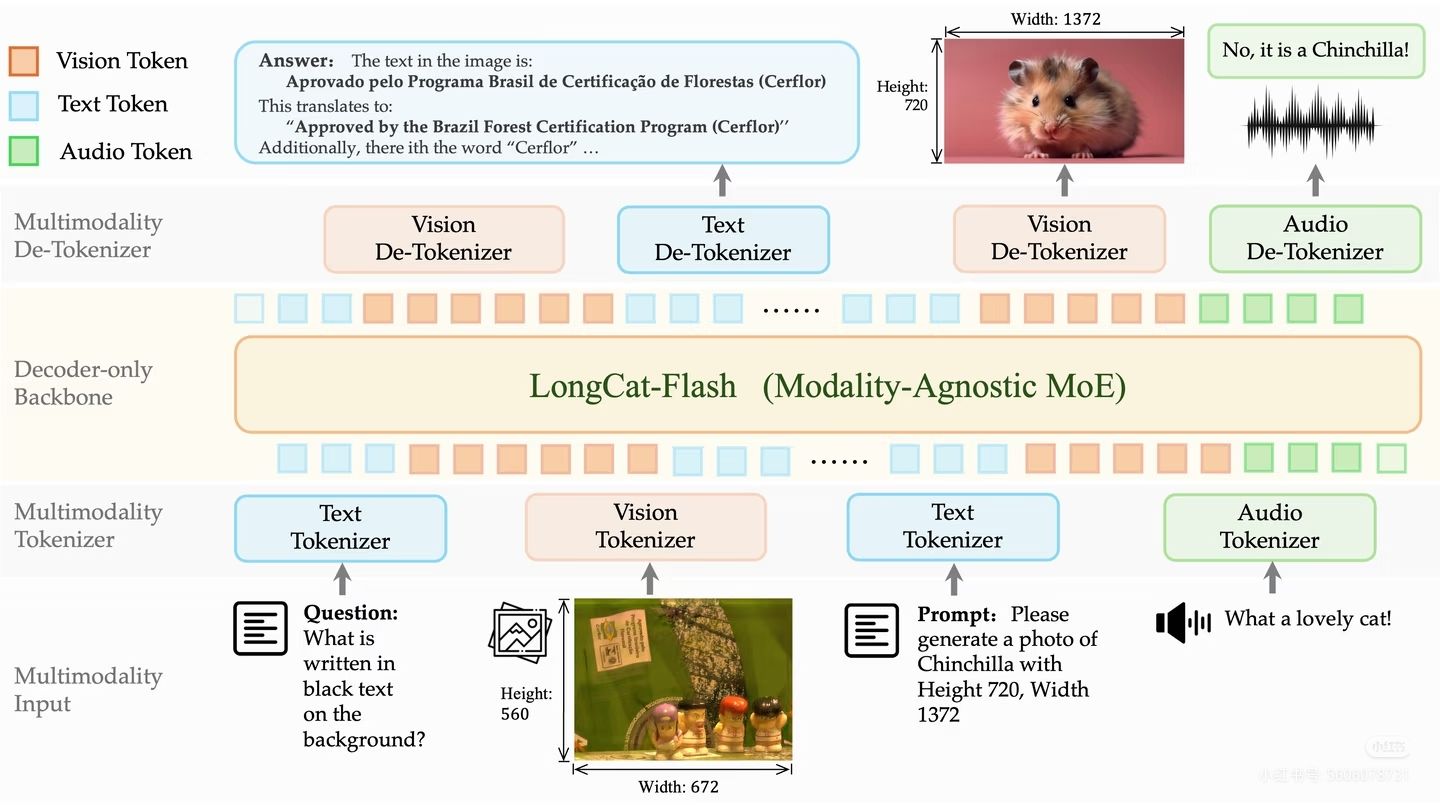
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and speech as native languages rather than secondary inputs, LongCat-Next aims to provide a more integrated approach to environmental perception and interaction. In a significant move for the developer community, Meituan has open-sourced both the core model and its discrete tokenizer. This initiative is intended to empower developers to build AI systems capable of perceiving, understanding, and acting within real-world contexts, marking a strategic step forward in Meituan's exploration of embodied AI and physical-world applications.
Key Takeaways
- Native Multimodality: LongCat-Next integrates vision and speech as "native languages," moving beyond traditional modular AI approaches.
- Open Source Commitment: Meituan has released the core LongCat-Next model and its discrete tokenizer to the global developer community.
- Physical World Focus: The model is specifically designed to explore the intersection of AI and the physical world, emphasizing perception and action.
- Developer Empowerment: By providing these tools, Meituan aims to facilitate the creation of AI that can interact meaningfully with real-world environments.
In-Depth Analysis
The Evolution of Native Multimodality
The release of LongCat-Next represents a significant shift in how AI models process diverse data types. Meituan describes the model's core philosophy as making vision and speech the "native language" of the AI. In traditional AI architectures, different modalities like text, image, and audio are often processed by separate encoders and then fused together. However, a "native" multimodal approach suggests a more unified architecture where the model learns to represent and process visual and auditory information with the same depth and fluidity as text. This integration is crucial for reducing information loss during translation between modalities and for achieving a more holistic understanding of complex environments.
By focusing on vision and speech as primary inputs, LongCat-Next is positioned to handle the nuances of the physical world more effectively. This native integration allows the model to potentially recognize patterns and context in real-time scenarios—such as navigating a physical space or understanding spoken commands in noisy environments—more naturally than models that rely on external adapters or secondary processing layers.
Open Sourcing the Discrete Tokenizer
A critical component of the LongCat-Next release is the open-sourcing of its discrete tokenizer. In the context of multimodal AI, a tokenizer is responsible for converting continuous data (like images or audio waves) into discrete units that the model can process. The decision to release the tokenizer alongside the model is a strategic move to lower the barrier to entry for developers.
Providing the discrete tokenizer allows researchers and engineers to understand exactly how LongCat-Next "sees" and "hears" the world. This transparency is vital for fine-tuning the model for specific industrial or commercial applications. By sharing the research core and the underlying tools, Meituan is fostering an ecosystem where the community can contribute to the model's evolution, potentially accelerating the development of specialized AI agents that can operate in diverse physical settings.
Bridging AI and the Physical World
Meituan's stated goal for LongCat-Next is to build AI that can "perceive, understand, and act upon the real world." This focus on the "physical world" aligns with the broader industry trend toward embodied AI—intelligence that is not confined to a screen but is integrated into robots, autonomous vehicles, or smart infrastructure.
The ability to not just analyze data but to "act" implies that LongCat-Next is designed with decision-making in mind. Whether it is optimizing delivery routes, assisting in warehouse logistics, or enhancing user interactions in physical retail spaces, the model serves as a foundational layer for AI that interacts with tangible objects and human environments. This exploration is a key part of Meituan's broader technological roadmap to integrate AI more deeply into daily physical services.
Industry Impact
The introduction of LongCat-Next has several implications for the AI industry. First, it reinforces the trend of major technology firms moving toward open-source contributions to establish their architectures as industry standards. By releasing a model focused on physical interaction, Meituan is carving out a niche in the competitive landscape of multimodal LLMs (Large Language Models).
Furthermore, the focus on native multimodality sets a benchmark for future research. As AI moves from digital-only applications to physical-world integration, the efficiency and accuracy of vision and speech processing become paramount. LongCat-Next provides a framework for how these modalities can be harmonized. For the developer ecosystem, this release provides high-quality, specialized tools that were previously proprietary, likely sparking a new wave of innovation in robotics and autonomous systems that require sophisticated environmental perception.
Frequently Asked Questions
Question: What makes LongCat-Next different from other multimodal models?
LongCat-Next is designed with vision and speech as its "native languages," meaning it is built from the ground up to process these modalities natively rather than as secondary additions. It is specifically optimized for applications that require the AI to perceive and act within the physical world.
Question: Why did Meituan open-source the discrete tokenizer?
Open-sourcing the discrete tokenizer allows developers to see how the model converts real-world visual and auditory data into processable information. This transparency enables more precise fine-tuning and helps the community build more compatible tools and applications based on the LongCat-Next architecture.
Question: What are the intended use cases for LongCat-Next?
While the model is a foundational research exploration, its design targets any application where AI needs to interact with the physical world. This includes areas like robotics, environmental perception, and any system that requires a deep, integrated understanding of visual and auditory cues to perform real-world tasks.