
Meituan Tech Team Launches LARYBench to Standardize Latent Action Representation Learning from Human Video Data
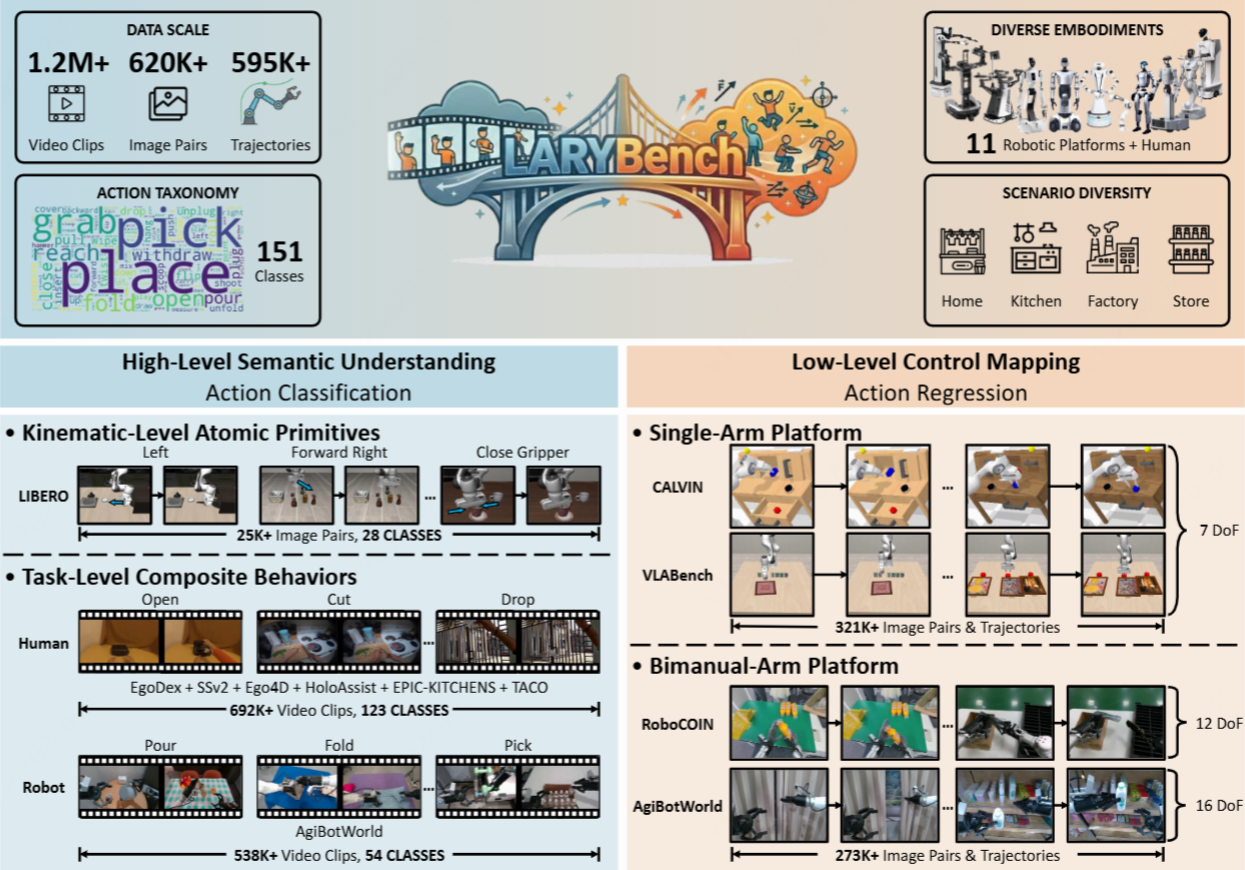
Meituan's technology team has introduced LARYBench (Latent Action Representation Yielding Benchmark), a groundbreaking system designed to evaluate how embodied AI learns action representations from large-scale visual datasets. The benchmark's initial findings indicate a paradigm shift: general-purpose vision models are demonstrating superior performance in action generalization and control precision compared to specialized expert models. Crucially, the research proves that embodied action representations can emerge naturally from human video data, providing a new pathway for developing more capable and adaptable robotic systems. By defining a metric similar to ImageNet for the field of embodied AI, LARYBench offers a systematic way to measure and improve how machines understand and execute physical actions based on visual observation.
Key Takeaways
- Introduction of LARYBench: A systematic evaluation benchmark designed to measure latent action representations learned from large-scale visual data.
- Superiority of General Models: Experimental results show that general vision models outperform specialized embodied AI expert models in both action generalization and control precision.
- Emergent Representations: The benchmark demonstrates that embodied action representations can successfully emerge from large-scale human video data.
- Standardization of Embodied AI: LARYBench aims to serve as a foundational metric, similar to the role ImageNet played for computer vision, specifically for the field of embodied action.
In-Depth Analysis
The Role of LARYBench in Embodied AI
The Meituan technology team has developed LARYBench (Latent Action Representation Yielding Benchmark) to address a critical gap in the development of embodied AI: the lack of a systematic way to evaluate how models learn to represent actions from visual input. In the same way that ImageNet revolutionized computer vision by providing a standardized dataset for object recognition, LARYBench is positioned to define the standards for latent action representation. By focusing on "latent" actions—those that are not explicitly labeled but are inferred from visual sequences—the benchmark allows researchers to quantify how well an AI understands the underlying mechanics of movement and interaction within a physical environment.
General Vision Models vs. Specialized Experts
One of the most significant findings revealed through LARYBench is the performance gap between general-purpose vision models and specialized embodied AI action expert models. Traditionally, the industry has relied on "expert models" trained specifically for robotic tasks or narrow embodied scenarios. However, LARYBench's experimental data suggests that general vision models, which are trained on broader and more diverse datasets, possess a superior ability to generalize actions across different contexts. These general models do not only excel in variety but also in control precision, suggesting that the features learned by broad-spectrum vision models are more robust and adaptable than those developed by niche, task-specific architectures.
Learning from Human Video: The Path to Emergence
The research highlights a pivotal shift in how embodied AI can be trained. LARYBench demonstrates that embodied action representations can "emerge" from large-scale human video data. This implies that AI does not necessarily need to be trained exclusively on robotic telemetry or specialized simulation data to understand physical actions. Instead, by observing the vast amount of human activity captured in video format, general vision models can distill the essence of movement and interaction. This emergence of action representation from passive observation of humans opens new doors for scaling AI training, as human video data is far more abundant and diverse than specialized robotic datasets.
Industry Impact
The introduction of LARYBench is likely to have a profound impact on the robotics and AI industries. By providing a clear metric for action generalization and control precision, it encourages a shift away from narrow, task-specific models toward more versatile foundation models. This could accelerate the development of general-purpose robots capable of performing a wide array of tasks in unpredictable human environments. Furthermore, the validation that human video data is a viable source for learning embodied actions reduces the data bottleneck currently facing the industry, potentially lowering the cost and complexity of training advanced embodied agents.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark created by Meituan's technology team to measure and guide the learning of general latent action representations from large-scale visual data, acting as a standard for the embodied AI field.
Question: Why are general vision models performing better than specialized expert models?
According to the LARYBench experiments, general vision models demonstrate better action generalization and control precision. This is likely because the diverse data they are trained on allows them to develop more robust representations that adapt better to various embodied tasks compared to models trained on narrow, specific datasets.
Question: Can robots really learn how to move just by watching human videos?
LARYBench's results indicate that embodied action representations can indeed emerge from large-scale human video data. This means that by analyzing human movements in videos, AI models can learn the underlying patterns of action necessary for embodied intelligence without needing explicit robotic training for every task.

