
Meituan Releases LongCat-Next: Open-Sourcing Native Multimodal AI for Physical World Interaction
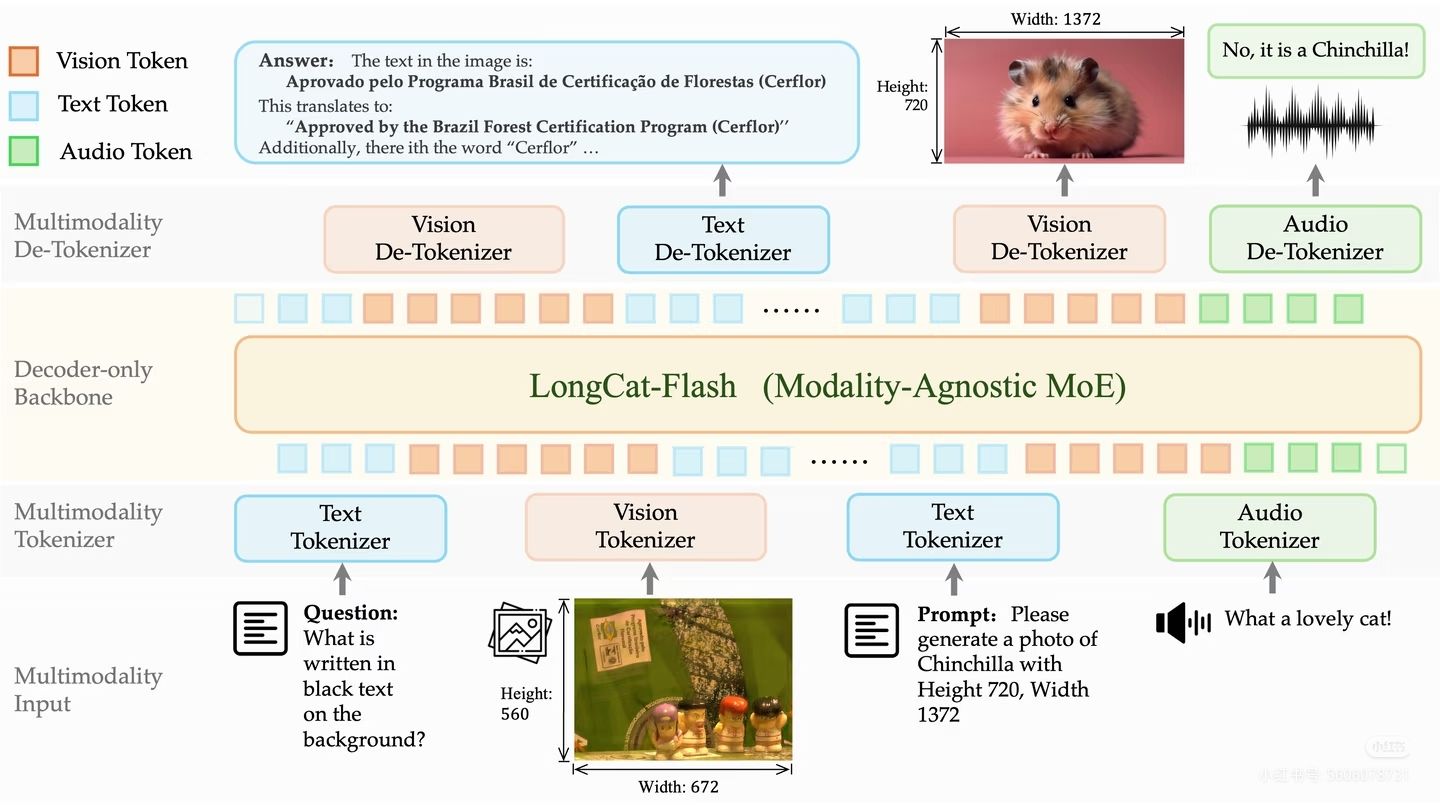
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and speech as "native languages," the model aims to enhance how AI perceives, understands, and interacts with its environment. Alongside the model, Meituan has open-sourced its discrete tokenizer, providing the developer community with essential tools to build systems capable of real-world perception and action. This strategic move represents a significant step in Meituan's exploration of embodied AI, moving beyond text-centric models to create a more integrated approach to multimodal intelligence.
Key Takeaways
- Native Multimodality: LongCat-Next integrates vision and speech as core components, treating them as "native languages" rather than secondary inputs.
- Open-Source Commitment: Meituan has released both the LongCat-Next model and its discrete tokenizer to the public developer community.
- Physical World Focus: The project is a primary exploration into AI that can perceive, understand, and act within the real, physical environment.
- Developer Empowerment: By open-sourcing the core research ideas, Meituan aims to facilitate the construction of AI that interacts with the world in a more human-like, multi-sensory manner.
In-Depth Analysis
The Shift Toward Native Multimodal Intelligence
The release of LongCat-Next by the Meituan technical team signals a pivotal shift in how multimodal AI is structured. Traditionally, many AI models have relied on text as a primary medium, with vision and speech processed through separate, often secondary, layers. LongCat-Next challenges this paradigm by positioning vision and speech as the "native languages" of the AI. This approach suggests a more unified architecture where different sensory inputs are processed with the same level of priority and integration as text. By making these modalities native, the model is designed to achieve a more intuitive understanding of the world, mirroring how biological entities process simultaneous sensory streams to navigate their surroundings.
Central to this release is the open-sourcing of the discrete tokenizer. In the context of multimodal models, a tokenizer is a critical component that converts raw data—such as images or audio waves—into a format that the model can process. By providing the discrete tokenizer alongside the LongCat-Next model, Meituan is offering the full technical stack necessary for developers to understand the underlying research logic. This transparency allows for a deeper exploration of how vision and speech can be discretized and integrated into a single, cohesive model, potentially setting a new standard for how multimodal systems are built and optimized for real-world tasks.
Bridging AI and the Physical World
Meituan describes LongCat-Next as an exploration on the path toward "Physical World AI." This terminology highlights a move away from AI that exists solely in digital or text-based environments toward "Embodied AI"—systems that can interact with and influence the physical realm. The goal is to create AI that does not just process data but actually perceives and acts upon the world. For a company like Meituan, which operates extensively in the physical space through delivery and local services, the development of AI that understands physical context is of paramount importance.
The decision to open-source these research findings is a strategic effort to accelerate the development of this field. By inviting developers to build upon LongCat-Next, Meituan is fostering an ecosystem where AI can be trained to handle the complexities of the real world, such as spatial awareness, auditory cues, and visual recognition. The focus is clearly on the practical application of AI: moving from theoretical understanding to active participation in physical environments. This release provides the foundational building blocks for the next generation of AI applications that require a sophisticated grasp of non-textual information.
Industry Impact
The open-sourcing of LongCat-Next is likely to have a significant impact on the AI industry, particularly in the sectors of robotics, autonomous systems, and multimodal research. By lowering the barrier to entry for high-quality native multimodal models, Meituan is enabling smaller research teams and independent developers to experiment with vision-speech integration. This could lead to a surge in specialized AI applications that require real-time environmental interaction. Furthermore, the emphasis on "native" multimodality pushes the industry to reconsider the limitations of text-heavy models, potentially accelerating the transition toward more holistic and sensory-aware artificial intelligence. As more developers adopt and refine the LongCat-Next framework, the collective understanding of how AI can serve as a bridge to the physical world is expected to expand rapidly.
Frequently Asked Questions
Question: What components of LongCat-Next have been open-sourced?
Meituan has open-sourced the core LongCat-Next model as well as its discrete tokenizer. This provides developers with both the primary model architecture and the tools necessary for processing multimodal data into a format the model can understand.
Question: What does "native multimodality" mean in the context of LongCat-Next?
Native multimodality refers to the model's ability to treat vision and speech as primary, inherent forms of data (like a "mother tongue") rather than translating them into text or using auxiliary plugins. This allows for more direct and integrated perception of different types of information.
Question: What is the primary goal of the LongCat-Next project?
The primary goal is to explore and develop AI that can perceive, understand, and act within the physical world. It aims to move AI beyond digital boundaries and into applications that require real-world interaction and sensory comprehension.