
Meituan LongCat Team Unveils LongCat-AudioDiT to Revolutionize Zero-Shot TTS Voice Cloning Technology
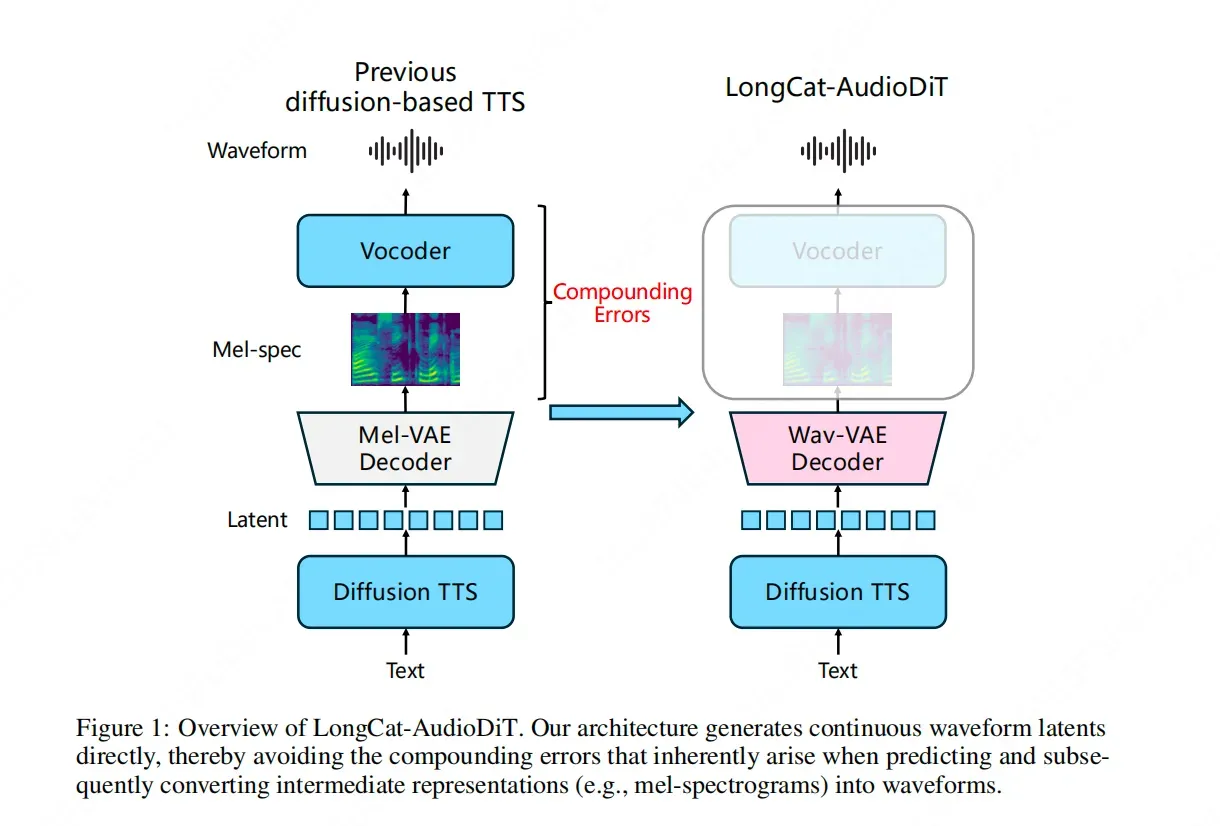
The Meituan LongCat team has officially released LongCat-AudioDiT, a groundbreaking model designed to push the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally changing the architecture of audio synthesis, the team has moved away from traditional intermediate representations such as Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based approach (AudioDiT). This strategic shift is intended to eliminate the cascading errors that often occur during the multi-stage data conversion processes in standard TTS systems. By teaching the AI to understand the inherent patterns and laws of sound directly, the model aims to provide a more seamless and high-fidelity voice cloning experience, addressing a major technical bottleneck in the field of artificial intelligence audio generation.
Key Takeaways
- Architectural Innovation: LongCat-AudioDiT completely abandons intermediate representations like Mel-spectrograms in favor of direct waveform latent space processing.
- Error Reduction: The model is specifically designed to block cascading errors at the source by removing the need for complex data conversion stages.
- Diffusion-Based Synthesis: It utilizes a diffusion model framework (AudioDiT) to allow the AI to learn the fundamental laws of sound directly.
- Zero-Shot Advancement: The technology focuses on breaking the performance ceiling for zero-shot voice cloning, enhancing the AI's ability to replicate voices with minimal data.
In-Depth Analysis
Eliminating Intermediate Representations
In traditional Text-to-Speech (TTS) systems, the process of converting text into audible speech usually involves several intermediate steps. One of the most common methods involves generating a Mel-spectrogram—a visual representation of the spectrum of frequencies of a signal as it varies with time—before converting that representation into a final waveform. However, the Meituan LongCat team identified this as a significant technical bottleneck.
With the introduction of LongCat-AudioDiT, the team has moved toward a more direct approach. By bypassing Mel-spectrograms and other intermediate representations, the model operates directly within the waveform latent space. This shift is not merely a simplification of the pipeline but a fundamental change in how the AI perceives and generates sound. By working in the latent space of the waveform itself, the model can maintain a higher degree of data integrity, ensuring that the nuances of the original sound are not lost or distorted through multiple layers of translation.
Solving the Problem of Cascading Errors
A primary motivation behind the development of LongCat-AudioDiT is the mitigation of "cascading errors." In multi-stage AI models, an error or approximation made in an early stage—such as the generation of a spectrogram—can be amplified in subsequent stages, such as the vocoding process that turns that spectrogram into audio. These errors often lead to artifacts, loss of clarity, or a lack of naturalness in the synthesized voice.
LongCat-AudioDiT addresses this by implementing a diffusion-based model that functions directly on the waveform latent space. By streamlining the process into a more end-to-end framework, the model effectively blocks the root cause of these conversion errors. This "direct-to-waveform" philosophy allows the AI to learn the inherent laws of sound patterns without the interference of artificial intermediate formats. The result is a more robust system capable of high-fidelity voice cloning, particularly in zero-shot scenarios where the model must replicate a voice it has never encountered during training based on a very short sample.
Industry Impact
The release of LongCat-AudioDiT by Meituan's LongCat team marks a significant milestone in the evolution of audio AI. By demonstrating the viability of direct waveform latent space diffusion for TTS, this research challenges the industry standard of relying on Mel-spectrograms. This could lead to a broader shift in how voice cloning models are designed, moving toward architectures that are more efficient and less prone to the technical artifacts associated with traditional conversion pipelines. For the AI industry, this means a potential leap in the quality of synthetic speech, making AI-generated voices more indistinguishable from human ones and expanding the possibilities for personalized digital assistants, content creation, and accessibility tools.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Answer: Unlike traditional models that use Mel-spectrograms as an intermediate step, LongCat-AudioDiT operates directly in the waveform latent space using a diffusion model, which prevents errors introduced during data conversion.
Question: What are "cascading errors" in the context of voice cloning?
Answer: Cascading errors occur when inaccuracies in early stages of audio generation (like creating a spectrogram) are carried over and amplified in later stages, resulting in lower-quality final audio. LongCat-AudioDiT avoids this by simplifying the generation process.
Question: Who developed LongCat-AudioDiT?
Answer: The model was developed and released by the Meituan LongCat team to improve the limits of zero-shot voice cloning technology.
