
Meituan LongCat Team Unveils LongCat-AudioDiT: Revolutionizing Zero-Shot TTS via Direct Waveform Latent Space Diffusion
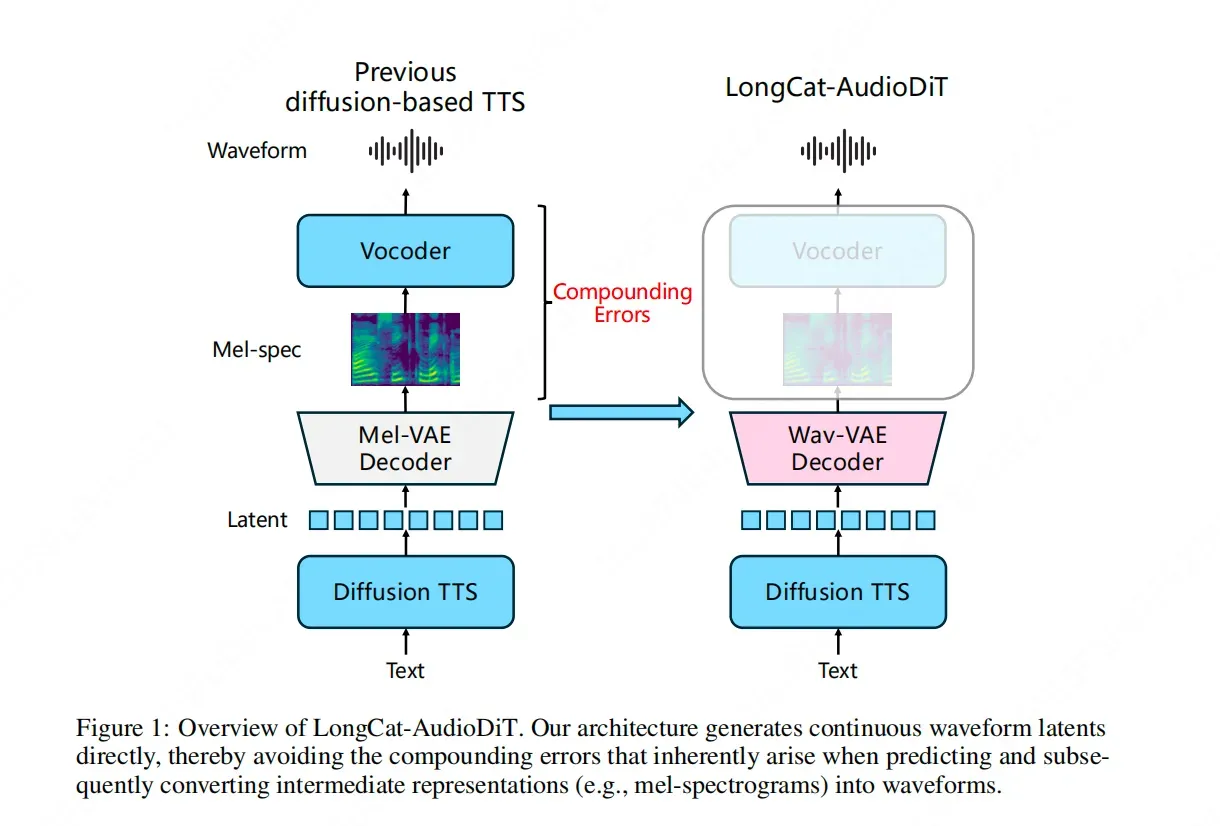
The Meituan LongCat team has officially released LongCat-AudioDiT, a pioneering model designed to overcome the technical limitations of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally redesigning the synthesis pipeline, the team has moved away from traditional intermediate representations like Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based architecture. This approach is specifically engineered to eliminate cascade errors caused by multi-stage data conversion, allowing the AI to learn the inherent laws of sound directly. This breakthrough promises to set a new upper limit for the fidelity and accuracy of voice cloning technology, providing a more streamlined and robust solution for high-quality audio generation.
Key Takeaways
- Elimination of Intermediate Steps: LongCat-AudioDiT abandons traditional Mel-spectrograms to prevent cascade errors during the TTS process.
- Direct Waveform Latent Space: The model operates within a latent representation of the actual waveform, allowing for more precise sound synthesis.
- Diffusion-Based Architecture: It utilizes a Diffusion Transformer (AudioDiT) to refine audio generation directly from text inputs.
- Enhanced Zero-Shot Performance: The technology aims to push the boundaries of how accurately AI can clone voices without prior specific training on the target speaker.
In-Depth Analysis
Breaking the Mel-spectrogram Bottleneck
For years, the field of Text-to-Speech (TTS) has relied heavily on intermediate representations, most notably the Mel-spectrogram. While effective, this multi-stage process—converting text to a spectrogram and then using a vocoder to convert that spectrogram back into a waveform—introduces what the Meituan LongCat team identifies as "cascade errors." Each conversion step acts as a potential point of data loss or distortion, which ultimately limits the fidelity of the cloned voice.
By introducing LongCat-AudioDiT, the team has effectively bypassed these intermediate hurdles. The model is designed to allow the AI to learn the fundamental laws of sound directly. By removing the need for a Mel-spectrogram, the system reduces the complexity of the pipeline and ensures that the nuances of the original audio signal are preserved more effectively. This direct-to-waveform approach represents a significant architectural shift in the pursuit of perfect voice cloning.
Diffusion Models in the Waveform Latent Space
The technical core of this innovation lies in the integration of Diffusion Transformers (DiT) within a waveform latent space. Diffusion models have proven highly successful in image generation, and the LongCat team has adapted this logic for high-fidelity audio. Instead of working with raw, high-dimensional audio data which is computationally expensive, the model operates in a compressed latent space that still captures the essential characteristics of the waveform.
This allows the AI to perform "Text-to-Speech" synthesis as a generative process that iteratively refines noise into a clear, structured audio signal. Because the model is learning the "laws of sound" rather than just mapping text to a visual representation of sound (like a spectrogram), it can achieve a higher level of naturalness. This is particularly crucial for zero-shot voice cloning, where the model must generalize its understanding of speech to replicate a voice it has only encountered briefly. The use of the AudioDiT framework ensures that the generated audio maintains temporal consistency and spectral accuracy without the artifacts often associated with traditional vocoding techniques.
Industry Impact
The release of LongCat-AudioDiT by Meituan's technical team marks a pivotal moment for the AI audio industry. By demonstrating that direct waveform latent space diffusion can outperform traditional pipelines, Meituan is challenging the industry standard of Mel-spectrogram-based synthesis. This has several implications:
- Fidelity Standards: The reduction of cascade errors sets a new benchmark for what is considered "high-fidelity" in AI-generated speech. As other players in the industry look to improve their TTS offerings, the shift toward direct waveform processing is likely to accelerate.
- Efficiency in Zero-Shot Cloning: The ability to clone voices more accurately with less data (zero-shot) opens up new possibilities for personalized digital assistants, localized content dubbing, and accessibility tools.
- Architectural Evolution: The success of the AudioDiT approach suggests that the Diffusion Transformer architecture is highly versatile, potentially leading to its adoption in other areas of audio processing beyond just TTS, such as music generation or environmental sound synthesis.
Frequently Asked Questions
What is the primary innovation of LongCat-AudioDiT?
The primary innovation is the removal of intermediate representations like Mel-spectrograms. LongCat-AudioDiT performs TTS directly in the waveform latent space using a diffusion model to avoid data conversion errors.
Why are "cascade errors" a problem in voice cloning?
Cascade errors occur when data is converted through multiple stages (e.g., text to spectrogram, then spectrogram to audio). Each stage can introduce small inaccuracies that accumulate, resulting in a final voice output that sounds less natural or loses the unique characteristics of the original speaker.
How does the waveform latent space improve audio quality?
By working in the waveform latent space, the AI can interact with a mathematically efficient representation of the actual sound wave. This allows the model to learn the fundamental patterns of audio directly, leading to higher precision and fewer artifacts compared to methods that rely on visual approximations of sound.
