
Meituan Releases LongCat-Next: Open-Sourcing a Native Multimodal Model for Physical World AI Interaction
Meituan's technical team has announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and speech as native languages rather than secondary inputs, LongCat-Next aims to enhance AI's ability to perceive, understand, and interact with real-world environments. The release includes the core model and its discrete tokenizer, providing the global developer community with the essential tools to build more sophisticated, context-aware AI systems. This initiative underscores Meituan's commitment to advancing AI capabilities in practical, physical applications through open-source collaboration and research transparency.
Key Takeaways
- Native Multimodality: LongCat-Next treats vision and speech as primary, native languages for the AI, rather than auxiliary inputs.
- Open Source Commitment: Meituan has open-sourced both the LongCat-Next model and its core discrete tokenizer to the developer community.
- Physical World Focus: The model is specifically designed to explore how AI can better perceive, understand, and act within the physical world.
- Developer Empowerment: By providing the research core, Meituan aims to enable developers to build AI systems with real-world environmental awareness.
In-Depth Analysis
Native Multimodality: Vision and Speech as Primary Inputs
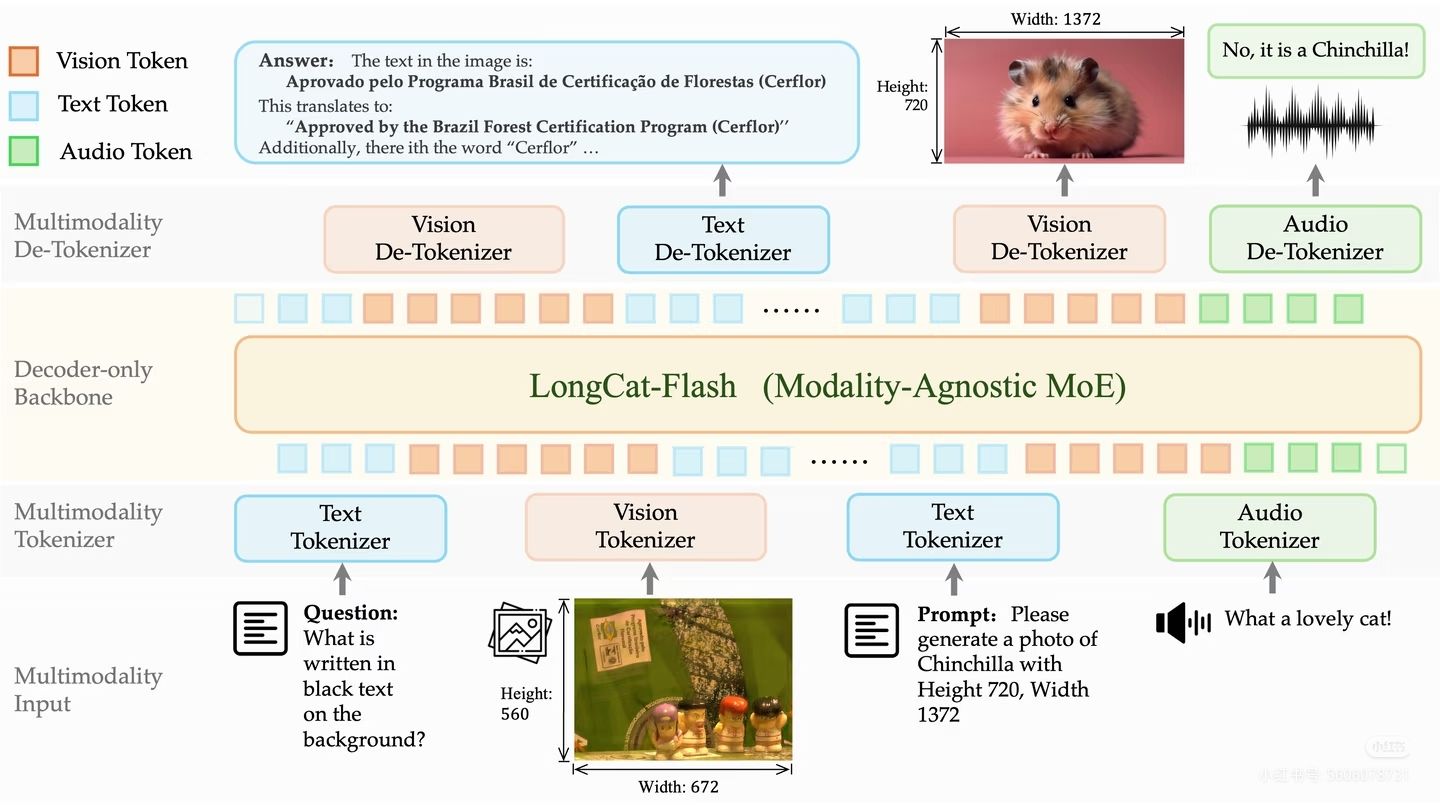
The release of LongCat-Next marks a significant shift in how multimodal AI is structured. Traditionally, many AI models have relied on text as the primary medium, with vision and speech processed through separate modules or adapters. Meituan’s approach with LongCat-Next redefines these sensory inputs as "native languages." This suggests a unified architecture where visual and auditory data are processed with the same level of depth and integration as textual information. By making vision and speech native to the model, LongCat-Next is designed to minimize the loss of information that often occurs during the translation between different modalities, potentially leading to a more nuanced understanding of complex, real-world scenarios.
Open-Sourcing the Discrete Tokenizer and Model Core
A critical component of this announcement is the decision to open-source the discrete tokenizer alongside the LongCat-Next model. In the context of multimodal AI, a tokenizer is responsible for converting raw data—such as images or audio waves—into discrete units that the model can process. By sharing this specific technology, Meituan is providing the "building blocks" of their research. This transparency allows developers to not only use the model but also understand the underlying mechanism of how it categorizes and interprets physical stimuli. This move is intended to foster a collaborative ecosystem where external researchers can build upon Meituan's foundational work to create specialized applications for various industries.
Industry Impact
Bridging the Gap to the Physical World
The development of LongCat-Next represents a strategic move toward "Physical World AI." While many current AI models excel at digital tasks like coding or writing, the next frontier involves AI that can operate effectively in physical environments—such as logistics, robotics, and autonomous services. Meituan’s focus on perception and action suggests that LongCat-Next is a step toward creating AI that can navigate and interact with the tangible world. By open-sourcing these tools, Meituan is positioning itself as a key contributor to the infrastructure of future AI systems that require a deep, native understanding of visual and auditory surroundings to perform physical tasks.
Frequently Asked Questions
Question: What is the primary goal of the LongCat-Next project?
The primary goal of LongCat-Next is to explore the path toward AI that can function in the physical world. It aims to provide a framework where AI can perceive, understand, and act upon real-world environments by treating vision and speech as native components of its intelligence.
Question: What specific components has Meituan open-sourced?
Meituan has open-sourced the core LongCat-Next model and its discrete tokenizer. These components represent the heart of their research into native multimodal AI, allowing developers to utilize and build upon their methodology for processing visual and auditory data.
Question: How does "native multimodality" differ from traditional AI processing?
Native multimodality means that the model is designed from the ground up to treat vision and speech as its primary languages. Unlike models that append visual or audio capabilities to a text-based core, LongCat-Next integrates these senses directly into its understanding, aiming for a more holistic and accurate perception of the physical world.