
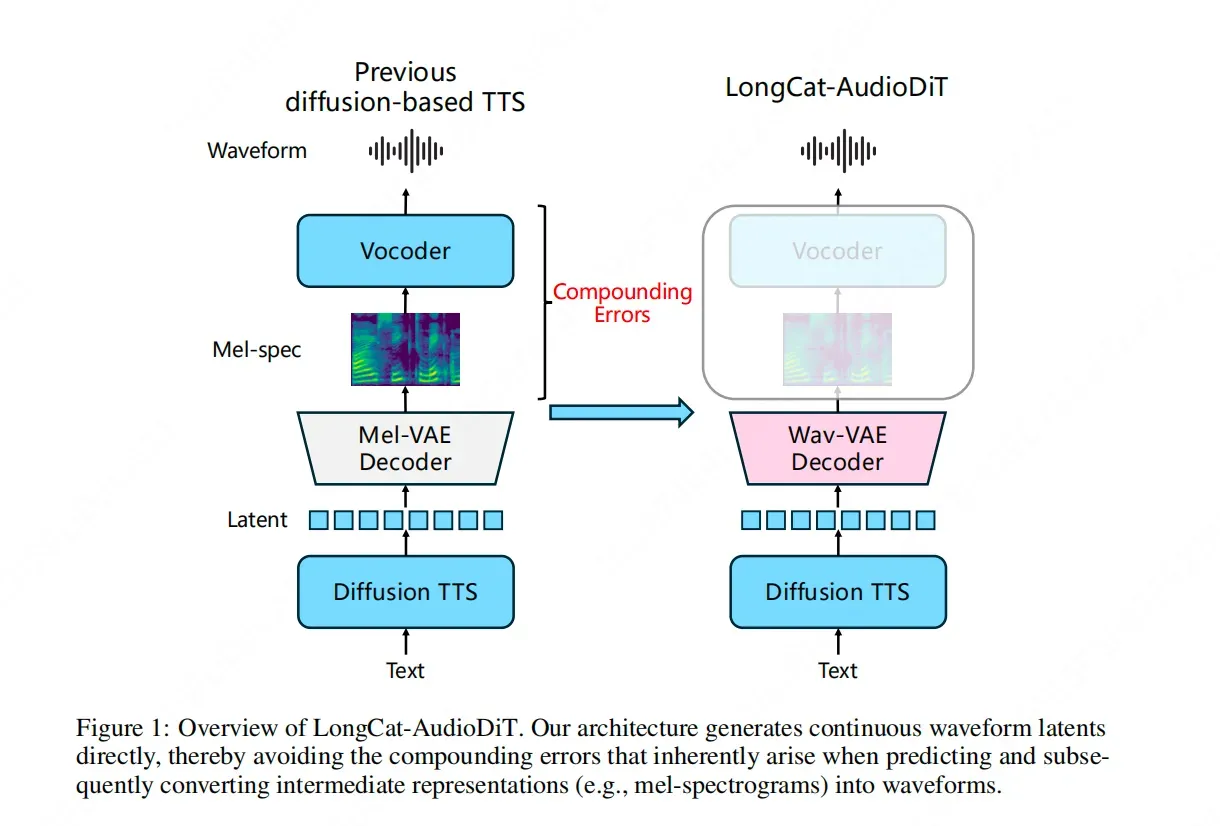
LongCat-AudioDiT: Meituan's Breakthrough in Zero-Shot TTS Voice Cloning via Waveform Latent Space Diffusion
Meituan's LongCat team has unveiled LongCat-AudioDiT, a pioneering model designed to push the boundaries of zero-shot voice cloning. By abandoning traditional intermediate representations such as Mel-spectrograms, the model operates directly within the waveform latent space using a diffusion-based framework. This strategic shift is designed to eliminate cascade errors inherent in multi-stage data conversion, allowing the AI to learn the fundamental laws of sound directly. The result is a more streamlined and accurate Text-to-Speech (TTS) process that enhances the fidelity of voice cloning. This development represents a significant technical leap in the field of audio synthesis, focusing on architectural purity to enhance the authenticity of generated speech and overcoming long-standing technical bottlenecks in the industry.
Key Takeaways
- Architectural Innovation: LongCat-AudioDiT completely abandons intermediate representations like Mel-spectrograms in favor of direct waveform latent space processing.
- Diffusion-Based Framework: The model utilizes a diffusion model to perform Text-to-Speech (TTS) tasks, ensuring high-fidelity audio generation.
- Error Reduction: By operating in the waveform latent space, the system prevents cascade errors typically caused by data conversion stages.
- Direct Sound Learning: The AI is designed to learn the inherent laws and patterns of sound directly, rather than through proxy representations.
- Zero-Shot Excellence: The technology aims to break the existing upper limits of zero-shot voice cloning performance.
In-Depth Analysis
Eliminating Intermediate Representations
In traditional Text-to-Speech (TTS) systems, the process often involves converting text into an intermediate visual or mathematical representation, such as a Mel-spectrogram, before a vocoder transforms that representation back into audible waveforms. While effective, this multi-step process introduces "cascade errors"—small inaccuracies at each stage that accumulate and degrade the final audio quality.
The Meituan LongCat team, through the development of LongCat-AudioDiT, has introduced a paradigm shift by removing these intermediate steps. By bypassing Mel-spectrograms, the model eliminates the primary source of these cumulative errors. This architectural decision ensures that the transition from text to speech is as direct as possible, preserving the integrity of the original sound patterns and resulting in a more authentic voice clone.
Waveform Latent Space and Diffusion Models
At the core of LongCat-AudioDiT is the use of a diffusion model operating within the waveform latent space. Diffusion models have gained prominence for their ability to generate high-quality, complex data by reversing a noise-addition process. By applying this technology directly to the latent space of the waveform, LongCat-AudioDiT allows the AI to capture the nuanced "laws of sound" directly from the source data.
This approach enables the model to understand and replicate the subtle textures and characteristics of a human voice without the loss of detail associated with traditional compression or representation methods. The focus on the waveform latent space allows the AI to focus on the fundamental properties of audio, which is critical for achieving high-fidelity zero-shot voice cloning—where the model must replicate a voice it has never encountered during its initial training phase.
Industry Impact
The release of LongCat-AudioDiT marks a significant milestone for the AI audio industry. By addressing the technical bottleneck of cascade errors, Meituan's LongCat team has set a new standard for the precision of zero-shot TTS. This technology has the potential to enhance various applications, from personalized digital assistants to high-quality content creation, by making voice cloning more accessible and realistic.
Furthermore, the move toward direct waveform processing suggests a new direction for future research in audio synthesis. As AI models move away from proxy representations and toward direct learning of physical sound properties, the gap between synthetic and human speech continues to narrow. This breakthrough reinforces the importance of architectural purity in developing next-generation generative AI.
Frequently Asked Questions
Question: What is the main advantage of LongCat-AudioDiT over traditional TTS models?
The primary advantage is the elimination of intermediate representations like Mel-spectrograms. By operating directly in the waveform latent space, LongCat-AudioDiT avoids the cascade errors that occur during data conversion, leading to higher-quality and more accurate voice cloning.
Question: How does the diffusion model contribute to the performance of LongCat-AudioDiT?
The diffusion model allows the AI to learn the complex patterns and laws of sound directly. By working within the waveform latent space, it can generate highly detailed and authentic audio, which is essential for breaking the performance limits of zero-shot voice cloning.
Question: Who developed LongCat-AudioDiT and what was their goal?
LongCat-AudioDiT was developed by the Meituan LongCat team. Their goal was to solve the technical bottleneck of data conversion errors and allow AI to learn the inherent laws of sound directly to improve the quality of Text-to-Speech systems.

