
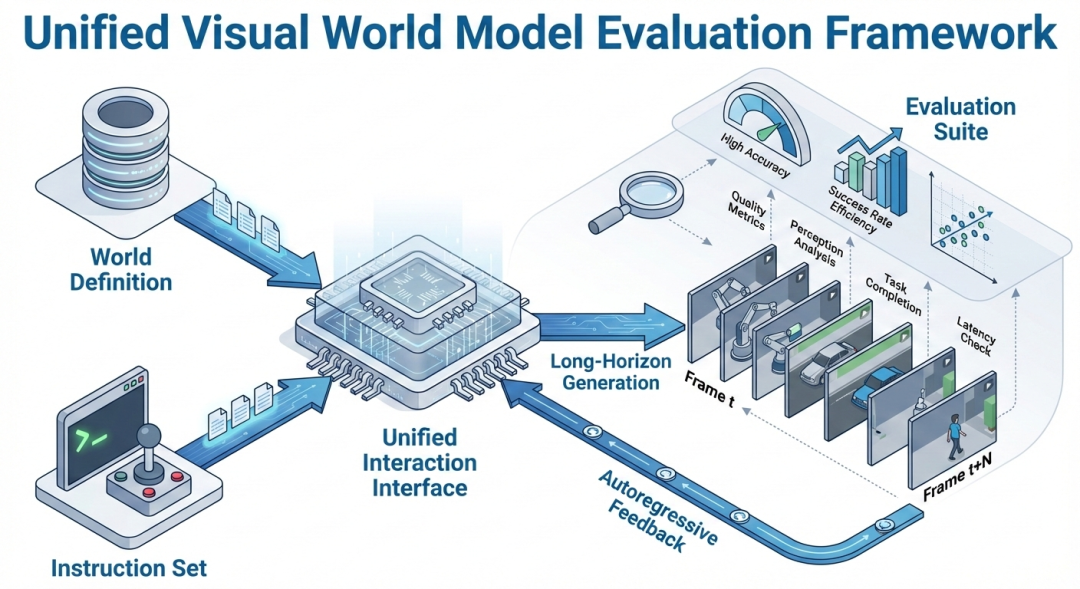
Meituan LongCat Team Launches WBench: The First Systematic Multi-Round Evaluation Benchmark for Interactive Video World Models
The Meituan LongCat team has officially introduced and open-sourced WBench, a groundbreaking evaluation benchmark designed to assess interactive video world models. Positioned as the industry's first systematic multi-round evaluation tool, WBench functions similarly to a "CT scanner," providing a deep diagnostic look into the capabilities of AI models. It specifically targets the transition from "passive viewing" to "active interaction," identifying the precise technical bottlenecks that prevent world models from achieving seamless interactivity. By offering a structured framework for multi-round testing, WBench allows researchers to pinpoint exactly where a model fails to maintain consistency or logic during interactive sequences. This open-source contribution marks a significant milestone in the quest to build more robust and responsive digital environments, shifting the focus from static video generation to dynamic, interactive world simulation.
Key Takeaways
- Pioneering Benchmark: Meituan's LongCat team has developed WBench, the first systematic multi-round evaluation benchmark specifically for interactive video world models.
- Diagnostic Precision: The tool is described as a "CT scanner" for AI, capable of pinpointing the exact locations where world models encounter technical hurdles.
- Interactive Evolution: WBench focuses on the critical transition of AI from "passive viewing" (observation) to "active interaction" (engagement).
- Open-Source Contribution: By open-sourcing WBench, the LongCat team provides the global AI community with a standardized method to measure the boundaries of world models.
- Systematic Evaluation: The benchmark utilizes multi-round interaction to test the logical consistency and environmental stability of AI-generated worlds.
In-Depth Analysis
Bridging the Gap Between Observation and Interaction
The development of world models has traditionally focused on the generation of high-quality video content, where the AI acts as a creator of a linear narrative. However, the Meituan LongCat team identifies a significant gap in this progression: the move from "passive viewing" to "active interaction." WBench is designed to bridge this gap by providing a systematic framework to evaluate how a model behaves when it is no longer just showing a scene, but responding to inputs within that scene. This shift is fundamental to the creation of truly immersive and functional world models. WBench serves as the primary tool to measure how well these models handle the complexities of a dynamic environment where actions have consequences and the world must react consistently over multiple rounds of engagement.
The "CT Scanner" Metaphor for AI Diagnostics
One of the most striking aspects of the WBench announcement is its description as a "CT scanner" for world models. In medical terms, a CT scanner provides a non-invasive way to look inside a complex system to find specific points of failure or disease. Similarly, WBench is applied to the "internal logic" of a world model. Instead of simply providing a surface-level score, it performs a deep diagnostic to see where the model "gets stuck." This level of granularity is essential for developers who need to understand whether a model's failure is due to a lack of temporal consistency, a misunderstanding of physical laws, or an inability to process multi-round feedback. By pinpointing these boundaries, WBench allows for a more scientific and targeted approach to model optimization.
Systematic Multi-Round Evaluation
Unlike traditional benchmarks that might evaluate a single action or a short clip, WBench introduces a systematic multi-round evaluation process. This is a critical distinction because the true test of a world model lies in its ability to maintain a coherent state over time. In a multi-round scenario, the AI must remember previous interactions and ensure that the current state of the world is a logical consequence of all prior events. WBench measures these boundaries, testing the limits of how many rounds of interaction a model can sustain before the "world" it has created begins to break down or lose its internal logic. This systematic approach provides a much more rigorous standard for what constitutes a successful world model.
Industry Impact
The introduction of WBench by the Meituan LongCat team has profound implications for the AI industry. By providing the first systematic benchmark for interactive world models, Meituan is setting a new standard for how these complex systems are evaluated. The open-source nature of WBench ensures that the entire industry can benefit from a unified metric, fostering competition and innovation in the development of interactive AI.
Furthermore, the focus on "active interaction" signals a shift in the industry's trajectory. As AI moves closer to applications in robotics, autonomous systems, and advanced simulations, the ability to interact with a world model becomes more important than the ability to simply generate a video. WBench provides the diagnostic tools necessary to reach these goals, helping the industry move past the current bottlenecks and toward a future where AI-driven environments are as responsive and consistent as the physical world.
Frequently Asked Questions
Question: What is the primary purpose of WBench?
WBench is designed to be a systematic multi-round evaluation benchmark for interactive video world models. It acts as a diagnostic tool to identify where models fail when transitioning from passive observation to active interaction.
Question: Who developed WBench and is it available to the public?
WBench was developed by the Meituan LongCat team. It has been open-sourced, making it available for the broader AI research community to use and contribute to.
Question: Why does WBench use a "multi-round" evaluation approach?
Multi-round evaluation is necessary to test the long-term consistency and logical stability of a world model. It ensures that the AI can handle a sequence of interactions while maintaining a coherent environment, which is a key requirement for advanced interactive applications.

