
Meituan Unveils LongCat-Next: Open-Sourcing Native Multimodal AI for Vision and Speech Integration
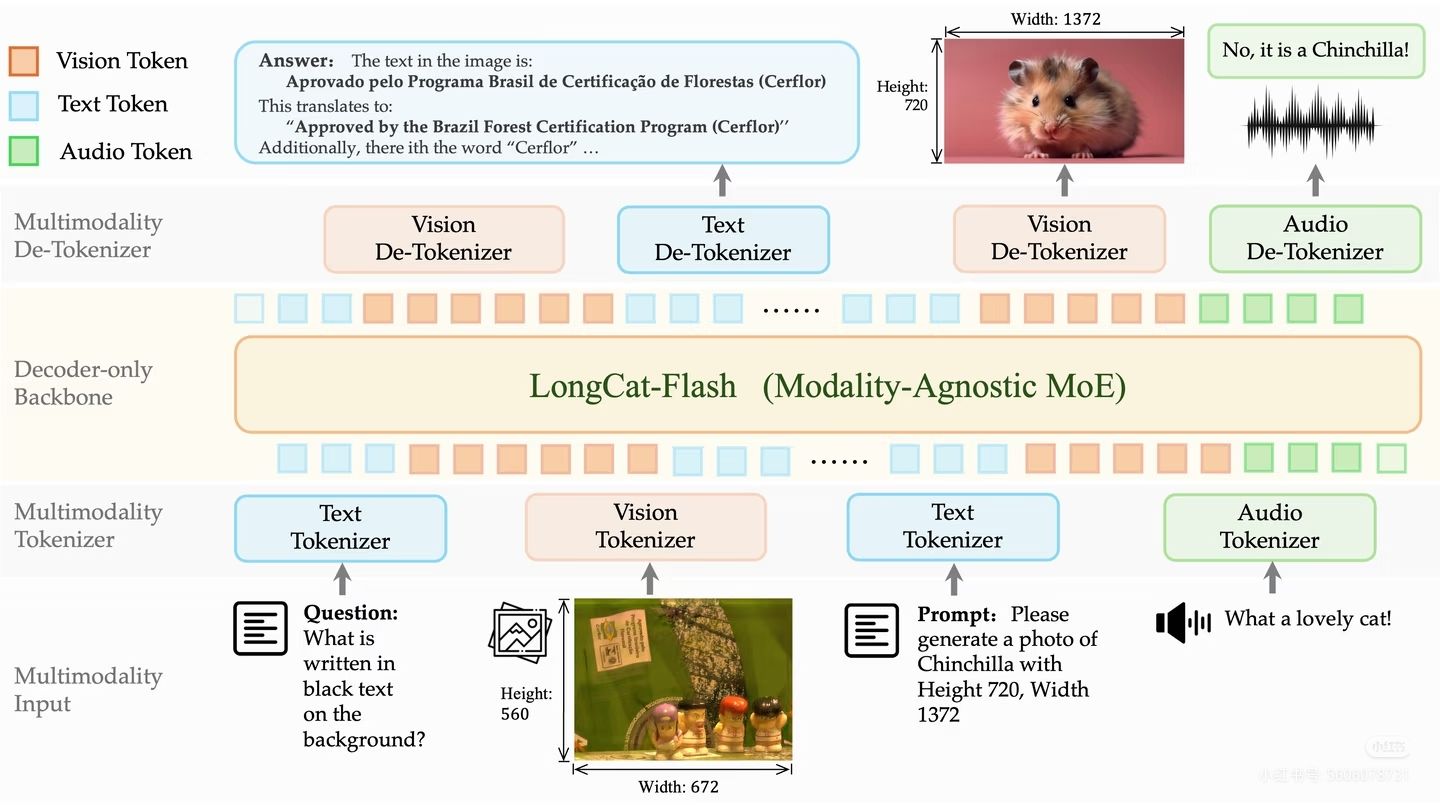
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a groundbreaking native multimodal model. Designed to treat vision and speech as fundamental "native languages," LongCat-Next represents a significant step in Meituan's journey toward creating AI that can interact with the physical world. By open-sourcing both the core model and its specialized discrete tokenizer, Meituan aims to empower the global developer community to build AI systems capable of perceiving, understanding, and acting within real-world environments. This initiative highlights a strategic shift toward embodied AI, where multimodal perception is integrated directly into the model's core architecture rather than being treated as an external add-on.
Key Takeaways
- Native Multimodality: LongCat-Next treats vision and speech as "native languages," integrating them directly into the model's core processing capabilities.
- Open Source Commitment: Meituan has open-sourced both the LongCat-Next model and its essential discrete tokenizer to foster community innovation.
- Physical World Focus: The model is specifically designed as an exploration into "physical world AI," focusing on perception and action in real environments.
- Developer Empowerment: The release is intended to help developers build AI that can truly perceive and understand the complexities of the physical world.
In-Depth Analysis
Redefining Multimodality: Vision and Speech as Native Languages
The release of LongCat-Next by the Meituan technical team marks a pivotal shift in how artificial intelligence handles diverse data types. Traditionally, multimodal AI systems have often relied on separate encoders for different inputs—such as vision or audio—which are then "translated" or mapped into a text-based large language model (LLM). However, Meituan’s approach with LongCat-Next suggests a more integrated architecture. By describing vision and speech as the AI's "native language," the team implies that the model does not merely translate these inputs into text but processes them with the same level of primacy and fluidity as a standard LLM processes words. This native integration is crucial for reducing information loss during the encoding process and allowing the model to develop a more holistic understanding of its environment.
The Strategic Importance of the Discrete Tokenizer
A standout feature of this announcement is the decision to open-source the discrete tokenizer alongside the LongCat-Next model. In the context of multimodal AI, a tokenizer is the component responsible for breaking down complex, continuous data—like the pixels in an image or the frequencies in a voice recording—into discrete units that the neural network can interpret. By providing the community with the specific discrete tokenizer used in LongCat-Next, Meituan is offering the "alphabet" and "grammar" that the model uses to read the physical world. This transparency allows researchers and developers to understand exactly how the model perceives sensory data, facilitating more precise fine-tuning and the development of specialized applications that require high-fidelity perception.
Bridging the Gap to Physical World AI
Meituan frames LongCat-Next as an exploration on the path to "physical world AI." This terminology points toward the burgeoning field of embodied AI, where the goal is to move beyond digital-only assistants and toward systems that can operate in, and interact with, the tangible world. For an AI to act effectively in a physical space—whether it is a delivery robot navigating a sidewalk or a system managing warehouse logistics—it must possess a deep, native understanding of visual and auditory cues. LongCat-Next is positioned as a foundational tool for this transition. The emphasis on "perceiving, understanding, and acting" suggests that Meituan views this model not just as a passive observer, but as a precursor to AI agents that can execute tasks and respond to real-time physical stimuli.
Industry Impact
The open-sourcing of LongCat-Next is likely to have a significant impact on the AI industry, particularly in the realms of robotics and autonomous systems. By lowering the barrier to entry for native multimodal research, Meituan is encouraging a more collaborative approach to solving the challenges of physical world interaction. This move may accelerate the development of more sophisticated embodied AI agents across various sectors, including logistics, retail, and service industries. Furthermore, Meituan's focus on native multimodality sets a technical benchmark for other industry players, potentially shifting the standard for future multimodal model architectures away from modular "bridge" systems toward more unified, native designs.
Frequently Asked Questions
Question: What makes LongCat-Next different from other multimodal models?
LongCat-Next is described as a "native" multimodal model, meaning it treats vision and speech as its primary languages rather than secondary inputs. This allows for a more integrated and seamless understanding of sensory data compared to models that use separate encoders to translate non-text data into a text-based format.
Question: Why did Meituan choose to open-source the discrete tokenizer?
The discrete tokenizer is a core component of the model's research methodology. By open-sourcing it, Meituan provides developers with the necessary tools to understand and replicate how the model perceives the physical world, enabling the community to build more effective AI systems that can interact with real-world environments.
Question: What is the primary goal of the LongCat-Next project?
The primary goal is to explore the development of AI that can function in the physical world. Meituan intends for LongCat-Next to serve as a foundation for AI that can perceive, understand, and act within the real world, moving beyond the limitations of purely digital or text-based artificial intelligence.