
Meituan LongCat Team Unveils LongCat-AudioDiT: Revolutionizing Zero-Shot TTS Voice Cloning via Waveform Latent Space Diffusion
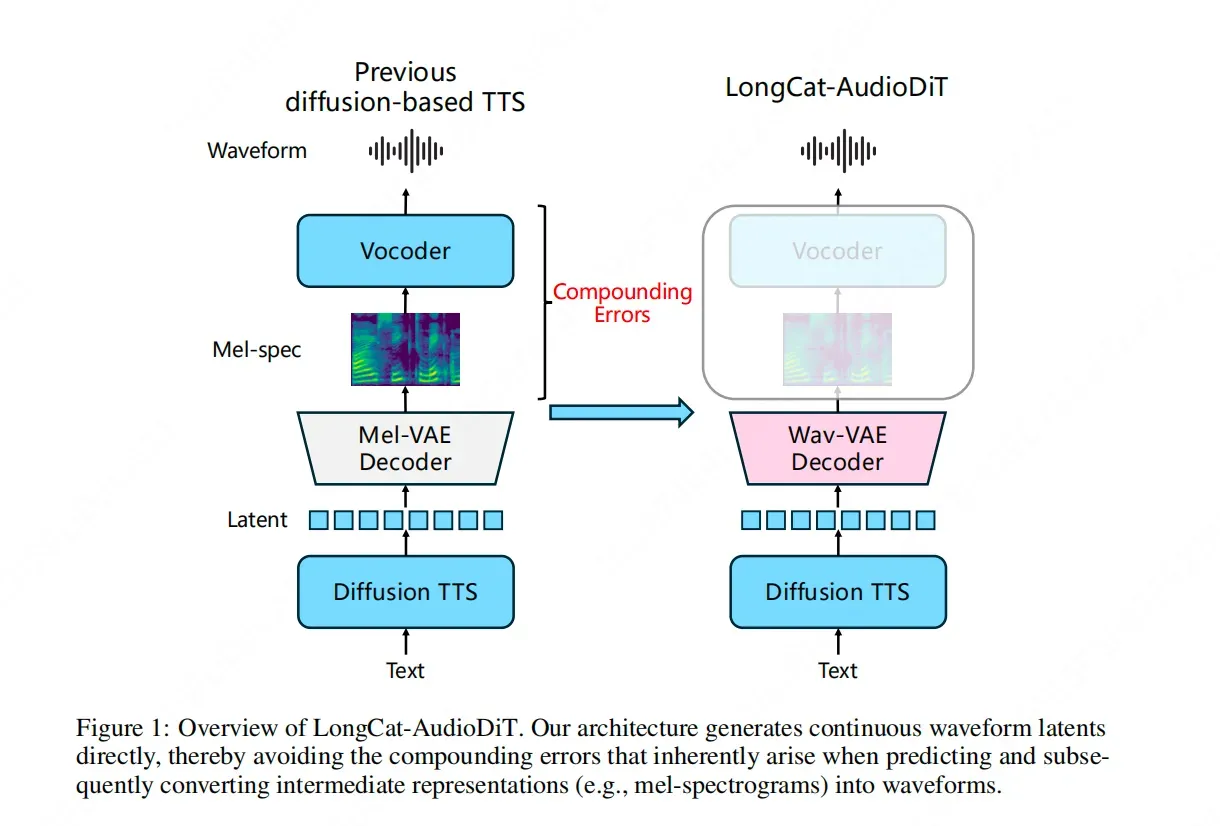
The Meituan LongCat team has officially introduced LongCat-AudioDiT, a pioneering model designed to push the boundaries of zero-shot Text-to-Speech (TTS) timbre cloning. By fundamentally changing the synthesis pipeline, the model abandons traditional intermediate representations such as Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based approach. This architectural shift is specifically engineered to eliminate the cascade errors typically associated with multi-stage data conversion processes. By allowing the AI to learn the inherent patterns of sound directly from the waveform, the model addresses long-standing technical bottlenecks in voice synthesis. This development represents a significant advancement for Meituan in achieving high-fidelity, seamless voice cloning, setting a new technical benchmark for the generative audio industry.
Key Takeaways
- Innovation in Architecture: Meituan's LongCat team has launched LongCat-AudioDiT, a model that bypasses traditional intermediate steps in speech synthesis.
- Direct Waveform Processing: The model operates directly in the waveform latent space, moving away from the industry-standard reliance on Mel-spectrograms.
- Diffusion Model Integration: It utilizes diffusion models to perform Text-to-Speech (TTS) tasks, aiming for higher fidelity in voice cloning.
- Error Reduction: By eliminating intermediate representations, the system prevents the accumulation of cascade errors during the data conversion process.
- Zero-Shot Capability: The technology is specifically designed to enhance the upper limits of zero-shot timbre cloning, allowing for more accurate voice replication.
In-Depth Analysis
Eliminating Intermediate Representations for Higher Fidelity
In the traditional landscape of Text-to-Speech (TTS) technology, the process often involves converting text into an intermediate representation—most commonly a Mel-spectrogram—before a separate vocoder transforms that representation into an audible waveform. While effective, this multi-stage approach introduces a significant technical bottleneck: cascade errors. Each conversion step acts as a potential point of data loss or distortion, which can ultimately degrade the quality of the synthesized voice.
Meituan’s LongCat-AudioDiT addresses this issue by completely discarding Mel-spectrograms. By removing these intermediate layers, the model allows the AI to engage with the sound's inherent laws directly. This streamlined approach ensures that the nuances of the original timbre are preserved, as there are no "middle-man" formats to introduce noise or inaccuracies. The focus on the waveform latent space represents a shift toward a more holistic understanding of audio data, where the model learns to generate sound in a way that is structurally closer to the final output.
Diffusion Models and the Waveform Latent Space
At the heart of LongCat-AudioDiT is the application of diffusion models within the waveform latent space. Diffusion models have gained prominence for their ability to generate high-quality, complex data by iteratively refining noise into a structured signal. By applying this logic to the waveform latent space rather than a visual representation of sound (like a spectrogram), LongCat-AudioDiT can capture the intricate temporal and frequency-based patterns of human speech more effectively.
This method is particularly potent for zero-shot timbre cloning. In zero-shot scenarios, the model must replicate a voice it has never encountered during training based on a very short audio sample. By operating in the latent space of the waveform itself, the model can more accurately map the unique characteristics of a specific voice. This direct learning mechanism allows the AI to bypass the limitations of traditional synthesis, resulting in a clone that is not only more realistic but also more robust against the artifacts typically found in synthetic speech.
Industry Impact
The introduction of LongCat-AudioDiT by Meituan marks a significant milestone in the evolution of generative AI and speech synthesis. By successfully navigating the technical challenges of direct waveform generation, Meituan is setting a new standard for how voice cloning models are built. The reduction of cascade errors is a major step forward for the industry, as it paves the way for more efficient and higher-quality audio production across various applications, from virtual assistants to content creation.
Furthermore, the focus on zero-shot capabilities addresses a growing demand for personalized AI interactions that do not require massive datasets for every individual user. As the industry moves toward more seamless human-AI communication, the ability to clone voices accurately and instantaneously using models like LongCat-AudioDiT will likely become a foundational technology. This breakthrough highlights the shift in AI research from optimizing existing pipelines to fundamentally reimagining the architecture of sound synthesis.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text to a Mel-spectrogram and then use a vocoder to create sound. LongCat-AudioDiT skips the Mel-spectrogram step entirely, operating directly in the waveform latent space using a diffusion model to reduce errors and improve quality.
Question: Why is the elimination of Mel-spectrograms important?
Mel-spectrograms are intermediate representations that can cause "cascade errors"—small mistakes in data conversion that add up and lower the final audio quality. By removing them, LongCat-AudioDiT prevents these errors and allows the AI to learn the direct patterns of sound.
Question: What is the benefit of using a diffusion model in this context?
Diffusion models are excellent at generating high-fidelity data from noise. In LongCat-AudioDiT, the diffusion model works within the waveform latent space to create more natural and accurate voice clones, especially in zero-shot scenarios where the AI has limited information about the target voice.
