
Meituan LongCat Team Unveils LongCat-AudioDiT: Redefining the Limits of Zero-Shot Voice Cloning Technology
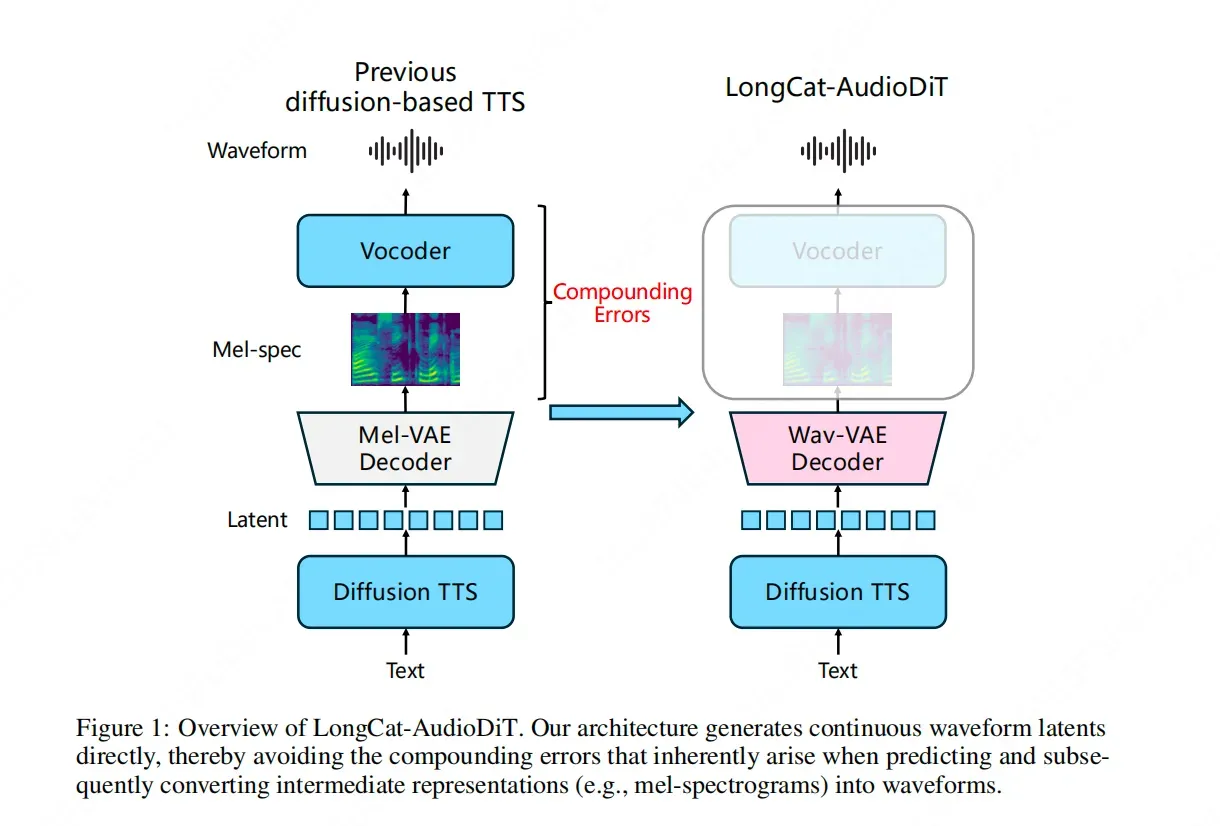
The Meituan LongCat team has officially announced the release of LongCat-AudioDiT, a groundbreaking Text-to-Speech (TTS) model designed to push the boundaries of zero-shot voice cloning. By fundamentally reimagining the audio synthesis pipeline, the model abandons traditional intermediate representations such as Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based architecture. This strategic shift is engineered to eliminate the cascade errors typically caused by multi-stage data conversions, allowing the AI to learn the inherent laws of sound directly. This development marks a significant milestone in the pursuit of high-fidelity, seamless voice mimicry without the need for extensive fine-tuning, potentially setting a new technical standard for the AI audio industry.
Key Takeaways
- Direct Waveform Latent Space Modeling: LongCat-AudioDiT bypasses traditional intermediate steps like Mel-spectrograms, operating directly in the waveform latent space.
- Elimination of Cascade Errors: By removing multi-stage data conversion processes, the model prevents the accumulation of errors that often degrade audio quality in traditional TTS systems.
- Diffusion-Based Architecture: The system utilizes a diffusion model (AudioDiT) to learn the underlying patterns and laws of sound directly from the source.
- Zero-Shot Voice Cloning Breakthrough: The model is specifically designed to enhance the upper limits of zero-shot voice cloning, enabling high-quality voice replication with minimal data.
In-Depth Analysis
The Departure from Mel-Spectrograms
For years, the field of Text-to-Speech (TTS) has relied heavily on intermediate representations, most notably Mel-spectrograms, to bridge the gap between text and audible sound. While effective, this multi-stage approach introduces a significant technical bottleneck: cascade errors. When a model first generates a Mel-spectrogram and then passes it to a separate vocoder to produce a waveform, inaccuracies in the first stage are inevitably amplified in the second.
Meituan's LongCat-AudioDiT represents a paradigm shift by completely discarding these intermediate representations. By operating directly within the waveform latent space, the model treats audio synthesis as a more unified process. This approach allows the AI to capture the nuances of sound without the loss of information that occurs during the conversion to and from frequency-domain representations. The result is a more robust system that maintains the integrity of the original voice's characteristics, which is crucial for high-fidelity zero-shot cloning.
Diffusion Models and the AudioDiT Architecture
The core of this innovation lies in the application of diffusion models to the waveform latent space. Diffusion models have already revolutionized image generation, and the LongCat team is now applying these principles to the complexities of human speech. The "AudioDiT" (Audio Diffusion Transformer) architecture suggests a fusion of diffusion processes with transformer-based modeling, allowing the system to handle long-range dependencies in audio data while maintaining the generative flexibility of diffusion.
By teaching the AI to learn the "laws of sound itself," the LongCat team is moving away from heuristic-based audio processing toward a more fundamental understanding of acoustics. This allows the model to skip the "middleman" of traditional audio engineering features and focus on the raw structural patterns of the waveform. This direct learning process is what enables the model to push the upper limits of zero-shot performance, as it can generalize the essence of a voice from a very limited sample more effectively than models constrained by fixed intermediate formats.
Overcoming Technical Bottlenecks in Voice Cloning
Zero-shot voice cloning—the ability to mimic a voice the model has never encountered during training using only a short prompt—is one of the most challenging tasks in AI audio. The primary obstacle has always been the trade-off between similarity and naturalness. Traditional systems often struggle to replicate the unique timbre and prosody of a target speaker because the conversion process through Mel-spectrograms acts as a filter that removes subtle acoustic details.
LongCat-AudioDiT addresses this by ensuring that the path from text to waveform is as direct as possible. By blocking the source of cascade errors, the model ensures that the latent features extracted from the target voice prompt are mapped directly onto the generated output. This architectural purity is intended to solve the "technical bottleneck" mentioned by the Meituan team, providing a path toward voice cloning that is indistinguishable from the original source, even in zero-shot scenarios.
Industry Impact
The introduction of LongCat-AudioDiT is likely to have a profound impact on the AI audio industry. By demonstrating that Mel-spectrograms are no longer a necessity for high-quality TTS, Meituan is challenging the established research trajectory of the last decade. This could lead to a broader industry shift toward end-to-end latent space modeling, potentially reducing the computational overhead and complexity of deploying high-performance TTS systems.
Furthermore, the improvement in zero-shot cloning capabilities opens up new possibilities for personalized AI assistants, localized content creation, and more immersive gaming experiences. As the technology matures, the ability to generate high-fidelity, personalized audio with minimal data will become a standard requirement, and LongCat-AudioDiT positions Meituan at the forefront of this evolution. The focus on reducing "cascade errors" also sets a new benchmark for quality assurance in generative audio, pushing other developers to reconsider their data conversion pipelines.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually generate an intermediate Mel-spectrogram before converting it into a waveform using a vocoder. LongCat-AudioDiT skips this intermediate step and operates directly in the waveform latent space using diffusion models, which prevents the accumulation of errors between different stages of the process.
Question: Why did the Meituan team decide to abandon Mel-spectrograms?
Mel-spectrograms are considered a source of "cascade errors." By removing them, the team aims to prevent the loss of detail and the introduction of artifacts that occur during the conversion between text, frequency representations, and final audio waveforms. This allows the AI to learn the direct laws of sound.
Question: What is the primary benefit of the waveform latent space approach for users?
The primary benefit is a significant improvement in the quality and accuracy of zero-shot voice cloning. Users can expect more realistic and higher-fidelity voice replication from shorter audio samples, as the model is better at capturing the fundamental characteristics of a voice without the interference of intermediate data formats.
