
Meituan Open Sources LongCat-Next: A Native Multimodal Model for Real-World AI Perception and Interaction
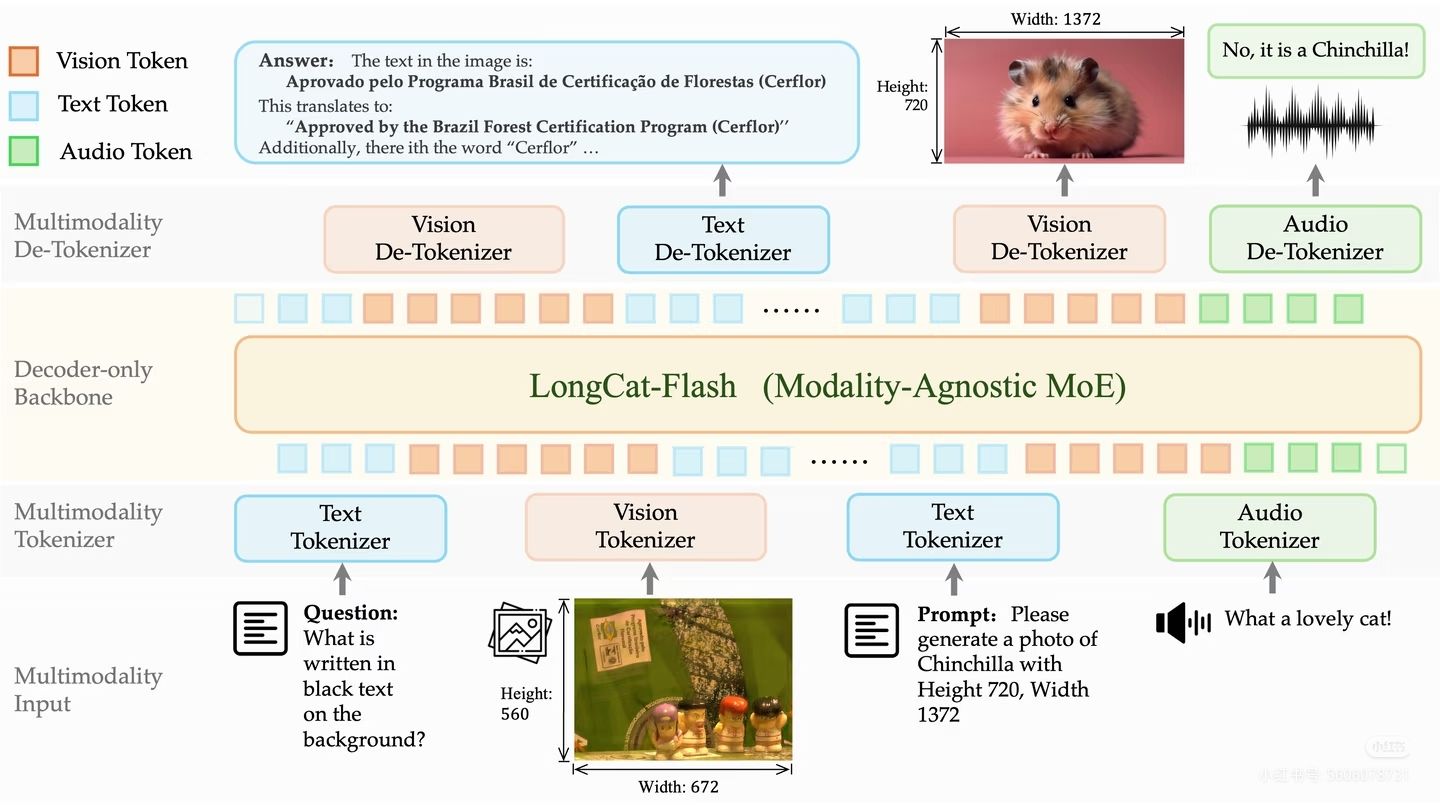
Meituan's technical team has officially released and open-sourced LongCat-Next, a native multimodal model designed to bridge the gap between AI and the physical world. By treating vision and voice as "native languages," this model aims to enhance how AI perceives and interacts with its environment. The release includes the core LongCat-Next model and its discrete tokenizer, providing developers with the tools to build systems capable of understanding and acting within real-world scenarios. This move marks a significant step in Meituan's exploration of physical-world AI applications, offering the global developer community a foundation for creating AI that can truly sense and respond to the complexities of the physical realm.
Key Takeaways
- Meituan has officially open-sourced LongCat-Next, a native multimodal model.
- The release includes both the core model and its specialized discrete tokenizer.
- The project focuses on enabling AI to perceive, understand, and interact with the physical world.
- Vision and voice are integrated as "native" components of the AI's processing architecture.
- The open-source move is intended to empower developers to build real-world AI applications.
In-Depth Analysis
Bridging the Physical and Digital Worlds
The release of LongCat-Next represents a strategic pivot toward what Meituan describes as "Physical World AI." Unlike traditional large language models that operate primarily within text-based or digital-only environments, Meituan's latest exploration seeks to bridge the gap between abstract computation and tangible interaction. By focusing on the ability to "perceive, understand, and act," the model is designed to handle the inherent complexities of the physical environment. This approach suggests a move toward systems where sensory input—specifically vision and voice—is not just an add-on but a fundamental part of the model's cognitive architecture. The goal is to move beyond simple data processing toward an AI that can navigate and influence the world around it.
The Role of the Discrete Tokenizer
A critical component of this release is the open-sourcing of the discrete tokenizer. In the context of multimodal AI, tokenizers are essential for converting raw sensory data, such as images or audio signals, into a discrete format that the model can process and analyze. By providing the community with the LongCat-Next discrete tokenizer, Meituan is lowering the technical barrier for developers to experiment with native multimodality. This allows for more seamless integration of different data types, supporting the core philosophy that vision and voice should be treated as "native languages" for the AI. This transparency in the research methodology allows developers to see exactly how the model interprets the physical world, fostering a deeper understanding of multimodal integration.
Native Multimodality as a Core Philosophy
Meituan's description of vision and voice as the "native languages" of AI highlights a shift in how multimodal models are constructed. In many previous iterations of AI, non-textual data was often translated or adapted into text-like structures. LongCat-Next, however, treats these inputs as primary sources of information. This "native" approach is intended to make the AI's understanding of the physical world more intuitive and efficient. By open-sourcing the research ideas behind this core concept, Meituan is encouraging a shift in the industry toward models that are built from the ground up to be multi-sensory, rather than being text-centric models with external plugins.
Industry Impact
Accelerating Real-World AI Applications
The decision to open-source LongCat-Next could have a profound impact on the AI development ecosystem. By sharing their core research ideas and tools, Meituan is fostering a collaborative environment for building AI that interacts with the real world. This move aligns with the broader industry trend toward open-source multimodal models, which accelerates innovation by allowing global developers to build upon existing frameworks. For the AI industry, this signals a shift toward more practical, sensor-aware applications that can eventually be deployed in service industries, logistics, or personal assistance. The availability of these tools allows smaller teams and independent researchers to contribute to the advancement of physical-world AI, which was previously dominated by large-scale labs.
The Open-Source Contribution to Multimodal Research
By releasing the model and its tokenizer, Meituan is contributing to the collective knowledge of the AI research community. Open-sourcing research ideas is a vital step in validating new approaches to multimodality. It allows for peer review, community-driven optimization, and the discovery of new use cases that the original creators might not have envisioned. As AI continues to evolve toward more complex interactions, the availability of native multimodal frameworks like LongCat-Next will be essential for establishing standards in how AI perceives and acts upon visual and auditory stimuli.
Frequently Asked Questions
Question: What exactly has Meituan open-sourced with the LongCat-Next project?
Meituan has released the core LongCat-Next model along with its discrete tokenizer. This provides the necessary framework for developers to understand the research methodology and build their own applications based on this native multimodal architecture.
Question: What is the primary goal of the LongCat-Next model?
The primary goal is to explore the path toward AI that can function effectively in the physical world. It aims to create systems that can perceive environmental stimuli, understand their context, and take meaningful actions within a real-world setting, moving beyond purely digital interactions.
Question: Why does Meituan refer to vision and voice as "native languages" for this model?
This terminology implies that the model is built from the ground up to process visual and auditory information directly, rather than relying on external translation layers or text-based proxies. This "native" approach is intended to make the AI's understanding of the physical world more intuitive and robust.