
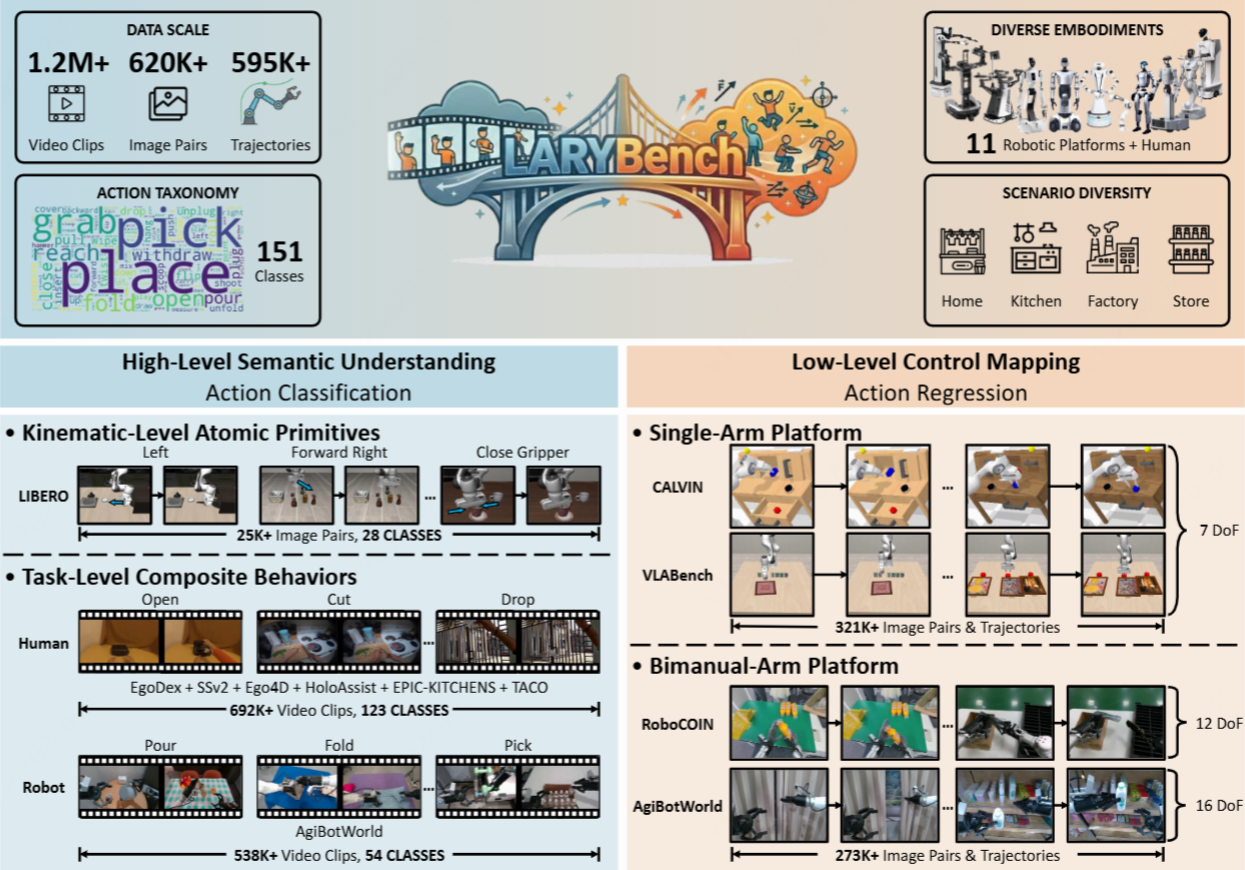
Meituan Technical Team Launches LARYBench to Standardize Latent Action Representation Learning from Human Video Data
The Meituan Technical Team has unveiled LARYBench (Latent Action Representation Yielding Benchmark), a systematic framework for evaluating general latent action representations derived from large-scale visual datasets. The benchmark's initial findings challenge the status quo of embodied AI development, showing that general-purpose vision models significantly surpass specialized action expert models in both generalization and control precision. Crucially, the research demonstrates that embodied action representations can emerge spontaneously from large-scale human video data, providing a new pathway for training robots and autonomous systems using existing non-robotic visual information. This breakthrough suggests that the future of embodied intelligence may lie in leveraging massive, diverse human video datasets rather than relying solely on specialized, task-specific robotic data.
Key Takeaways
- Introduction of LARYBench: A systematic evaluation benchmark designed to guide the learning of general latent action representations from large-scale visual data.
- Superiority of General Models: Experimental results indicate that general vision models outperform specialized embodied AI expert models in both action generalization and control precision.
- Emergence from Human Video: The research proves that embodied action representations can emerge naturally from large-scale human video data, reducing the reliance on specialized robotic datasets.
- Defining the 'ImageNet' for Actions: LARYBench aims to provide a standardized metric for embodied intelligence, similar to how ImageNet revolutionized visual recognition.
In-Depth Analysis
A Systematic Framework for Latent Action Representation
The release of LARYBench (Latent Action Representation Yielding Benchmark) by the Meituan Technical Team marks a significant milestone in the field of embodied AI. For years, the industry has struggled with the lack of a standardized, systematic way to evaluate how well an AI model understands and represents physical actions. LARYBench addresses this gap by providing a benchmark specifically focused on latent action representations. By utilizing large-scale visual data, the benchmark allows researchers to measure how effectively a model can translate visual information into actionable, implicit representations. This systematic approach is essential for moving beyond ad-hoc testing and toward a more rigorous, scientific evaluation of embodied intelligence.
General Vision Models vs. Specialized Action Experts
One of the most striking findings from the LARYBench experiments is the performance gap between general vision models and specialized embodied action expert models. Traditionally, the development of embodied AI has favored the creation of "expert" models—AI systems trained specifically for a narrow set of physical tasks or robotic controls. However, LARYBench demonstrates that general-purpose vision models, which are trained on vast and diverse visual datasets, actually exhibit superior performance. These general models show higher levels of action generalization, meaning they can adapt to new, unseen tasks more effectively than their specialized counterparts. Furthermore, they provide greater control precision, which is critical for the fine-grained movements required in robotics and autonomous systems.
The Power of Large-Scale Human Video Data
Perhaps the most transformative insight provided by the LARYBench research is the discovery that embodied action representations can emerge from large-scale human video data. Previously, it was often assumed that to teach a robot how to move, one needed data specifically recorded from robots or through complex simulation environments. The findings associated with LARYBench suggest that the rich, diverse movements captured in human videos contain enough latent information for AI models to learn generalizable action representations. This "emergence" of action understanding from non-robotic data opens up a massive repository of existing video content for training the next generation of embodied AI, potentially accelerating the development of robots that can function in complex, human-centric environments.
Industry Impact
The introduction of LARYBench is poised to shift the focus of the AI industry from specialized model architecture toward the utilization of large-scale, general-purpose visual training. By proving that general vision models are more effective at action generalization and precision, Meituan's research encourages a more unified approach to computer vision and robotics. This could lead to a significant reduction in the cost and complexity of training embodied AI, as developers can now leverage existing human video datasets rather than investing heavily in specialized data collection. Furthermore, LARYBench provides the industry with a much-needed "yardstick" to measure progress, likely sparking a new wave of competition and innovation in latent action representation, much like ImageNet did for the field of image classification a decade ago.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark designed to measure and guide the learning of general latent action representations from large-scale visual data, specifically for the field of embodied AI.
Question: Why are general vision models performing better than specialized models in this benchmark?
According to the research, general vision models demonstrate superior action generalization and control precision. This suggests that the broad knowledge captured by general models during large-scale training is more effective for complex action representation than the narrow focus of specialized expert models.
Question: Can AI learn how to move just by watching human videos?
Yes, the LARYBench results show that embodied action representations can emerge from large-scale human video data. This means that models can learn the underlying structure of physical actions by observing human movements, which can then be applied to robotic control and other embodied tasks.

