
Meituan LongCat Team Unveils LongCat-AudioDiT: Advancing Zero-Shot TTS Voice Cloning via Waveform Latent Space Diffusion
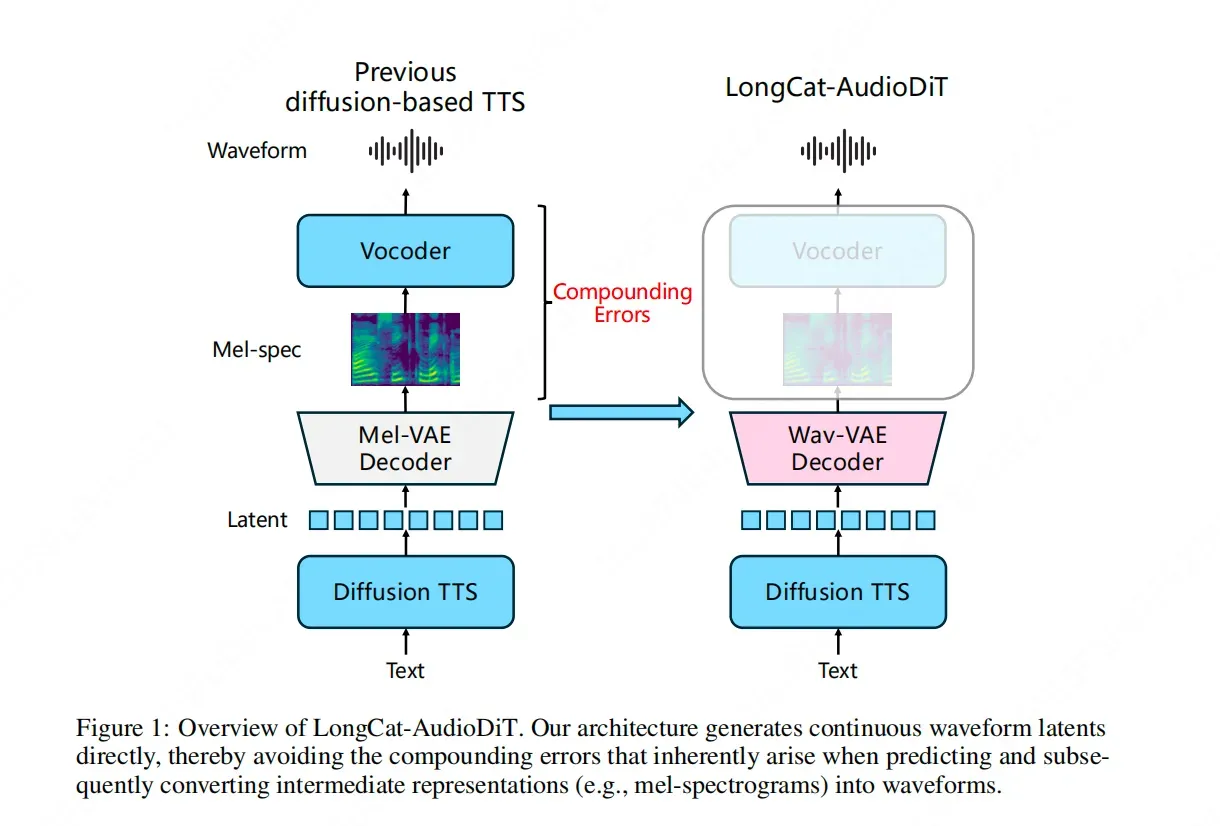
The Meituan LongCat team has officially announced the release of LongCat-AudioDiT, a sophisticated model designed to redefine the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally shifting the synthesis process, the model abandons traditional intermediate representations like Mel-spectrograms in favor of operating directly within the waveform latent space. Utilizing a diffusion-based framework, LongCat-AudioDiT aims to capture the inherent patterns of sound more effectively while eliminating the cascade errors typically associated with multi-stage data conversion. This breakthrough represents a significant technical evolution in speech synthesis, focusing on high-fidelity voice replication and structural simplicity in AI audio generation.
Key Takeaways
- Release of LongCat-AudioDiT: Meituan's LongCat team has launched a new model specifically targeting the limitations of zero-shot voice cloning.
- Direct Waveform Latent Space Processing: The model bypasses traditional intermediate steps, such as Mel-spectrogram generation, to work directly in the waveform latent space.
- Diffusion-Based Architecture: LongCat-AudioDiT utilizes diffusion models to learn and generate speech patterns, enhancing the naturalness of the output.
- Elimination of Cascade Errors: By removing intermediate data conversion stages, the model prevents the accumulation of errors that often degrade audio quality in traditional TTS pipelines.
- Focus on Zero-Shot Capabilities: The architecture is optimized to clone voices with high accuracy without requiring extensive fine-tuning on specific target speakers.
In-Depth Analysis
Breaking the Mel-Spectrogram Bottleneck
For years, the standard pipeline for Text-to-Speech (TTS) has relied heavily on intermediate representations, most notably the Mel-spectrogram. While effective, this approach introduces a two-stage process: first converting text to a spectrogram, and then using a vocoder to convert that spectrogram back into a playable waveform. The Meituan LongCat team identified this as a primary source of "cascade errors"—where inaccuracies in the first stage are amplified in the second, leading to robotic or distorted audio.
LongCat-AudioDiT represents a paradigm shift by abandoning these intermediate representations entirely. By operating directly in the waveform latent space, the model allows the AI to learn the fundamental laws of sound and vibration without the lossy compression inherent in Mel-spectrograms. This direct approach ensures that the nuances of a specific voice—the unique timbre and prosody—are preserved from the initial generation phase through to the final output.
Diffusion Models in the Latent Space
The core of LongCat-AudioDiT’s innovation lies in its use of a Diffusion Transformer (DiT) architecture applied to audio. Diffusion models have seen massive success in image generation, and the LongCat team has successfully adapted this logic to the complex, temporal nature of human speech. By performing diffusion within a latent space rather than on raw audio samples directly, the model maintains computational efficiency while achieving the high-fidelity results required for professional-grade voice cloning.
This method allows the model to "denoise" a representation of the voice based on text input and a short reference sample. Because it learns the underlying distribution of sound patterns rather than just mapping text to frequency charts, the resulting audio exhibits a level of organic realism that traditional models struggle to replicate. This is particularly crucial for "zero-shot" scenarios, where the model must clone a voice it has never encountered during its initial training phase.
Solving the Cascade Error Problem
In traditional TTS systems, the transition between different data formats—from text to phonemes, phonemes to spectrograms, and spectrograms to waveforms—creates multiple points of failure. Each conversion step acts as a filter that can strip away the subtle details of a human voice. LongCat-AudioDiT’s architecture is designed to "block the source" of these errors.
By streamlining the process into a more direct path from text to waveform latent space, the model ensures that the structural integrity of the audio is maintained. This reduction in complexity does not just improve sound quality; it also simplifies the training and deployment pipeline, potentially allowing for more robust performance across diverse languages and speaking styles. The focus remains on the AI's ability to grasp the "rules of sound" themselves, rather than just memorizing how to draw a picture of a sound wave.
Industry Impact
The introduction of LongCat-AudioDiT signals a significant shift in the competitive landscape of AI speech synthesis. By proving that direct waveform latent space diffusion is viable for zero-shot voice cloning, Meituan is setting a new technical benchmark for the industry. This approach likely reduces the need for massive, perfectly labeled datasets of Mel-spectrogram pairs, instead favoring models that can generalize from the raw physics of sound.
For the broader AI industry, this suggests a move toward more integrated, end-to-end architectures that minimize human-designed intermediate features. As zero-shot cloning becomes more accurate and less prone to conversion errors, the applications for personalized AI assistants, high-quality content localization, and accessibility tools will expand significantly. The "art of voice cloning" is moving away from approximation and toward a more fundamental understanding of acoustic patterns.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text into an intermediate Mel-spectrogram before turning it into sound. LongCat-AudioDiT skips this intermediate step and works directly in the waveform latent space using a diffusion model, which helps avoid errors and improves voice quality.
Question: What are "cascade errors" in voice synthesis?
Cascade errors occur when a mistake or loss of detail in one part of the AI process (like creating a spectrogram) is carried over and made worse in the next part (like turning that spectrogram into audio). LongCat-AudioDiT eliminates these by using a more direct generation process.
Question: What does "zero-shot" mean in the context of LongCat-AudioDiT?
Zero-shot means the model can clone a person's voice using only a very short sample, even if it has never heard that specific person's voice during its training. LongCat-AudioDiT is designed to excel at this by understanding the general patterns of human sound.
