
Meituan LongCat Team Open-Sources WBench: The First Systematic Multi-Round Benchmark for Interactive Video World Models
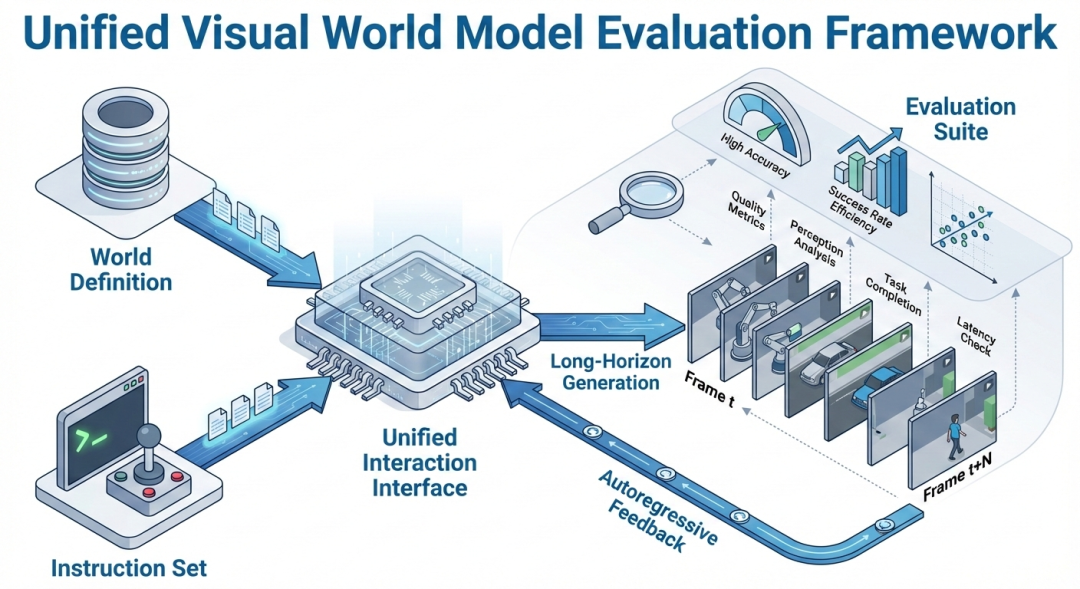
The Meituan LongCat team has officially released and open-sourced WBench, a groundbreaking systematic multi-round evaluation benchmark specifically designed for interactive video world models. Positioned as a diagnostic "CT scanner" for the AI industry, WBench is engineered to identify the specific technical limitations encountered as world models transition from passive observation to active, multi-turn interaction. By testing the boundaries of these models across diverse scenarios—ranging from lunar environments to cybernetic cities—WBench provides a rigorous framework for assessing how AI perceives and interacts with simulated worlds. This open-source initiative aims to provide the research community with a precise tool to measure and overcome the bottlenecks currently hindering the development of truly interactive and responsive world models.
Key Takeaways
- First of its Kind: WBench is the industry's first systematic multi-round evaluation benchmark focused specifically on interactive video world models.
- Diagnostic Precision: The tool acts as a "CT scanner," allowing developers to pinpoint exactly where world models fail during the transition from passive viewing to active interaction.
- Open-Source Contribution: Developed by Meituan's LongCat team, the benchmark has been made open-source to facilitate industry-wide progress in world modeling.
- Multi-Round Interaction: Unlike traditional benchmarks, WBench emphasizes multi-round evaluation to test the sustained interactive capabilities of AI models.
- Broad Scope: The benchmark measures model boundaries across a variety of complex scenarios, including lunar landscapes and futuristic urban environments.
In-Depth Analysis
Defining the Boundaries of World Models
The emergence of WBench by the Meituan LongCat team marks a significant shift in how the AI industry evaluates "world models." Traditionally, many models have been assessed based on their ability to generate or predict video content in a passive manner—essentially "watching" or "re-creating" a scene. However, the true potential of a world model lies in its ability to facilitate active interaction. WBench is designed to measure the exact boundaries of these capabilities, exploring how well a model can maintain consistency and logic when subjected to interactive prompts.
By utilizing scenarios such as "Moonwalk" and "Cyber City," WBench tests the limits of spatial reasoning, physical consistency, and environmental persistence. The benchmark seeks to answer a fundamental question: at what point does the model's understanding of the world break down when a user begins to interact with it? This focus on the "boundaries" of the model provides a clear map of current technological constraints.
The "CT Scanner" Approach to AI Evaluation
One of the most compelling aspects of WBench is its functional design as a diagnostic tool. The LongCat team describes WBench as a "CT scanner" for world models. This analogy suggests a level of granular, internal inspection that goes beyond surface-level performance metrics. In the context of AI development, a "CT scan" implies that WBench can look "inside" the interaction loop to identify specific failure points.
As models move from "passive viewing" to "active interaction," they often encounter bottlenecks related to temporal consistency, multi-turn logic, and the ability to respond to dynamic inputs. WBench’s systematic multi-round evaluation framework is specifically built to catch these errors. By subjecting a model to multiple rounds of interaction, the benchmark can reveal whether a model's performance degrades over time or if it can successfully navigate the complexities of a sustained, interactive environment. This diagnostic capability is essential for researchers who need to know not just that a model failed, but exactly where and why it failed.
Industry Impact
The introduction of WBench is poised to have a significant impact on the development of interactive AI. By providing the first systematic multi-round evaluation benchmark, Meituan is filling a critical gap in the current AI research ecosystem. Standardized benchmarks are the primary drivers of progress in the field, and WBench offers a specialized yardstick for the next generation of video-based world models.
Furthermore, the decision to open-source WBench ensures that the entire research community can benefit from these diagnostic capabilities. This transparency encourages a collaborative approach to solving the "interaction bottleneck," potentially accelerating the timeline for creating AI that can truly understand and interact with the physical or simulated world in real-time. As industry players strive to move beyond simple video generation toward complex, interactive simulations, WBench will likely serve as a foundational tool for measuring success and identifying the next frontiers of world model research.
Frequently Asked Questions
Question: What is WBench and who developed it?
WBench is the first systematic multi-round evaluation benchmark designed for interactive video world models. It was developed and open-sourced by the LongCat team within Meituan's technical department.
Question: Why is WBench compared to a "CT scanner"?
It is compared to a "CT scanner" because it is designed to precisely diagnose and locate the specific technical bottlenecks that occur when a world model attempts to transition from passive observation to active, multi-round interaction.
Question: What kind of scenarios does WBench use for evaluation?
WBench evaluates models across a diverse range of environments, specifically mentioning scenarios that span from lunar settings ("Moonwalk") to futuristic urban landscapes ("Cyber City") to test the boundaries of AI understanding.

