
Meituan LongCat Team Unveils LongCat-AudioDiT: A Breakthrough in Zero-Shot TTS Voice Cloning Technology
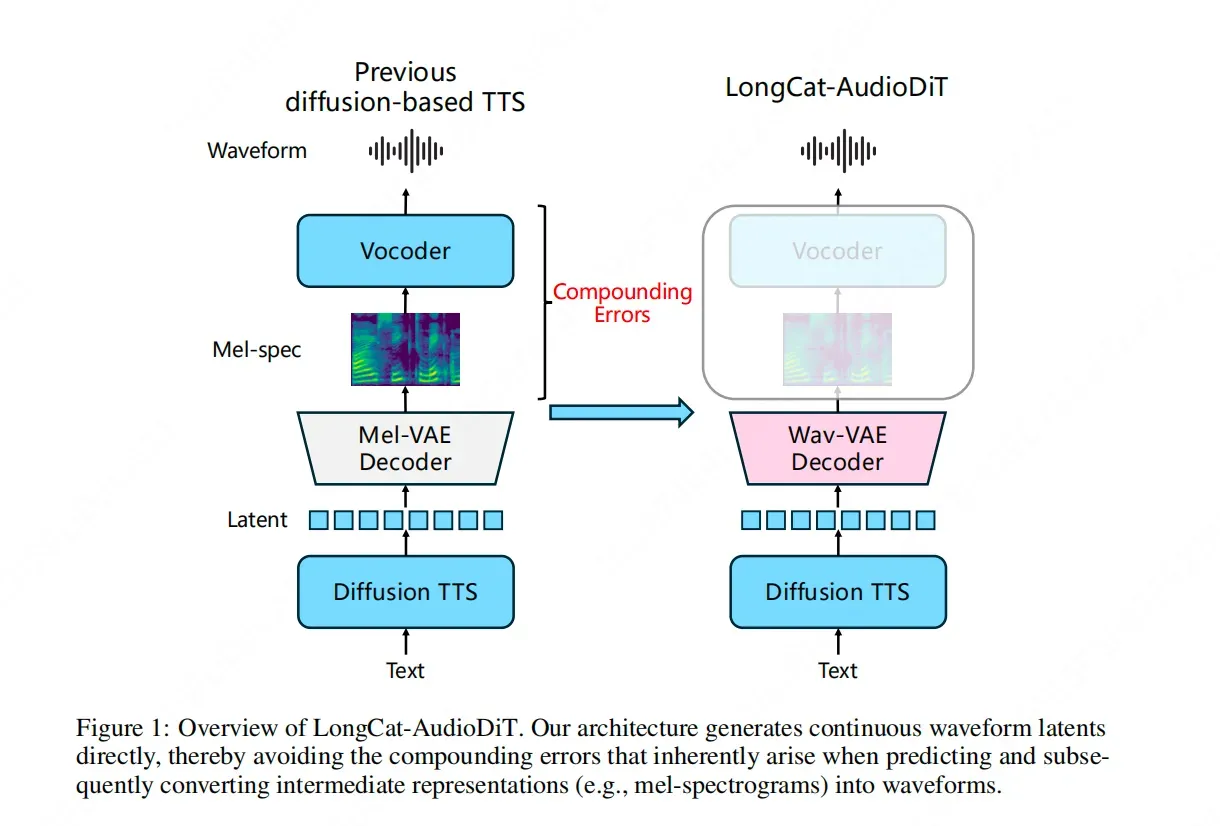
The Meituan LongCat team has officially released LongCat-AudioDiT, a pioneering model designed to push the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally redesigning the synthesis pipeline, the team has moved away from traditional intermediate representations like Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based architecture. This strategic shift is intended to eliminate the cascade errors typically associated with multi-stage data conversion processes. By allowing the AI to learn the inherent laws of sound directly, the model aims to provide a more seamless and high-fidelity voice cloning experience, representing a significant technical leap in the field of generative audio and speech synthesis.
Key Takeaways
- Direct Waveform Latent Space Operation: LongCat-AudioDiT bypasses traditional intermediate steps, operating directly where sound laws are most inherent.
- Elimination of Mel-spectrograms: The model removes the reliance on Mel-spectrograms to prevent the accumulation of cascade errors during the TTS process.
- Diffusion-Based Architecture: Utilizing a diffusion model (AudioDiT), the system learns the fundamental patterns of audio directly from the source.
- Enhanced Zero-Shot Capabilities: The architecture is specifically designed to break the existing performance ceilings of zero-shot voice cloning.
In-Depth Analysis
Overcoming the Bottleneck of Intermediate Representations
In traditional Text-to-Speech (TTS) systems, the process of converting text into audible speech often involves multiple stages, most notably the generation of Mel-spectrograms as an intermediate representation. While effective, this multi-step approach introduces a significant technical bottleneck: cascade errors. Each stage of conversion—from text to spectrogram, and then from spectrogram to waveform—carries the risk of data loss and distortion.
The Meituan LongCat team identified this as a primary hurdle in achieving high-fidelity voice cloning. With the introduction of LongCat-AudioDiT, the team has made the radical decision to abandon these intermediate representations entirely. By operating directly in the waveform latent space, the model ensures that the AI interacts with the raw essence of sound. This direct approach is designed to block the root cause of conversion errors, ensuring that the synthesized output remains as close to the original acoustic laws as possible.
The Power of Diffusion in Waveform Latent Space
At the heart of this breakthrough is the integration of a diffusion model within a latent space specifically tuned for waveforms. The "AudioDiT" (Audio Diffusion Transformer) framework allows the AI to learn the complex, non-linear laws of sound without the "filter" of traditional audio processing techniques.
By focusing on the waveform latent space, LongCat-AudioDiT can capture the nuances of a voice—its timbre, pitch, and rhythm—more accurately than systems that rely on simplified visual representations of sound. This allows the model to achieve a higher "upper limit" for zero-shot voice cloning. In a zero-shot scenario, where the model must clone a voice it has never encountered during training based on a very short sample, the ability to understand the fundamental laws of sound becomes the deciding factor in the quality and authenticity of the output.
Industry Impact
The release of LongCat-AudioDiT by Meituan's technical team signals a shift in the AI audio industry toward more integrated, end-to-end synthesis models. By proving that intermediate steps like Mel-spectrograms can be bypassed, Meituan is setting a new technical benchmark for other researchers and companies in the TTS space.
For the broader AI industry, this innovation suggests that the future of generative media lies in reducing the complexity of the pipeline and allowing models to learn from the most fundamental data representations available. As zero-shot voice cloning becomes more accurate and less prone to the artifacts caused by cascade errors, the potential applications in personalized digital assistants, content creation, and accessibility tools will expand significantly. This model demonstrates that the path to "human-like" AI audio involves a deeper, more direct understanding of the physics of sound.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text into an intermediate format called a Mel-spectrogram before turning it into sound. LongCat-AudioDiT skips this intermediate step and works directly in the waveform latent space using a diffusion model, which prevents errors that happen during data conversion.
Question: Why did the Meituan team decide to abandon Mel-spectrograms?
The team identified that using intermediate representations like Mel-spectrograms creates "cascade errors." These are errors that build up at each stage of the conversion process. By removing these steps, the model can learn the laws of sound directly and produce higher-quality voice clones.
Question: What is the significance of "Zero-Shot" in this context?
Zero-shot refers to the ability of the AI to clone a voice using only a small sample of audio that it has never seen before. LongCat-AudioDiT is designed to break the current performance limits of this technology, making the cloned voices sound more natural and accurate without needing extra training on that specific person's voice.
