
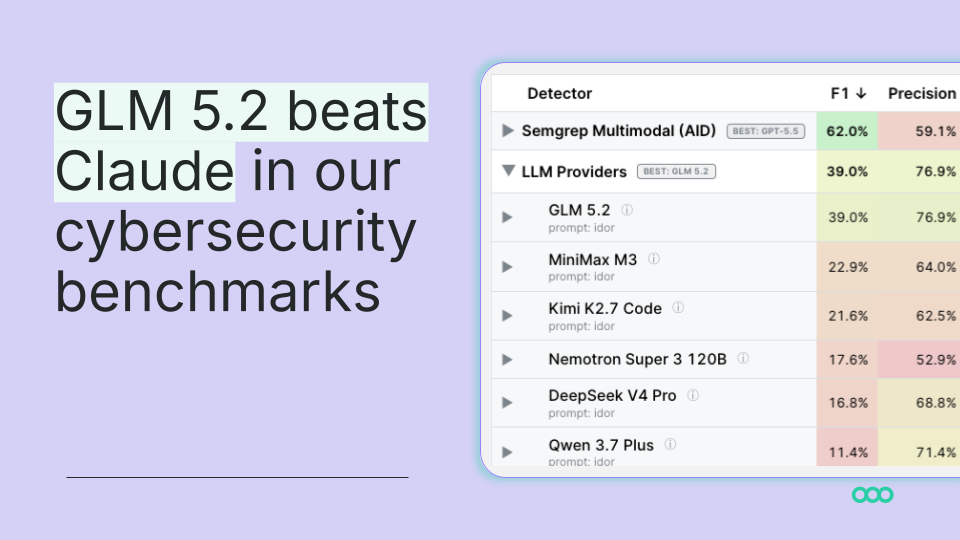
GLM 5.2 Outperforms Claude Opus 4.8 in Semgrep Cyber Benchmarks for Open-Weight AI Models
In a significant shift for the artificial intelligence landscape, Semgrep's latest cyber security benchmarks have revealed that GLM 5.2, an open-weight model, has surpassed the performance of Anthropic's Claude Opus 4.8. The testing, conducted by security researcher Katie Paxton-Fear, focused on models provided with only a prompt, highlighting the raw reasoning capabilities of open-weight alternatives in specialized technical domains. This revelation coincides with the launch of Semgrep Multimodal, a new initiative designed to integrate AI reasoning with traditional rule-based detection. The results suggest that for specific cyber security applications, open-weight models are now rivaling or exceeding the performance of leading proprietary models, potentially changing how organizations approach AI-driven security and code analysis.
Key Takeaways
- Benchmark Breakthrough: GLM 5.2 has officially outperformed Claude Opus 4.8 in Semgrep's specialized cyber security benchmarks.
- Open-Weight Dominance: The results highlight that the best open-weight options are now capable of beating top-tier proprietary models when given identical prompts.
- Semgrep Multimodal Launch: Semgrep has introduced a multimodal approach that combines AI reasoning with deterministic rule-based analysis for enhanced threat detection.
- Prompt-Only Performance: The testing focused on the inherent capabilities of models without external data augmentation, showcasing the strength of GLM 5.2's underlying architecture.
In-Depth Analysis
The Shift Toward Open-Weight Excellence
The recent benchmark results published by Semgrep, authored by security researcher Katie Paxton-Fear, mark a pivotal moment in the evolution of Large Language Models (LLMs) for technical applications. The headline achievement—GLM 5.2 beating Claude Opus 4.8—challenges the long-held assumption that proprietary, closed-source models inherently maintain a performance lead over open-weight alternatives. In these specific cyber benchmarks, GLM 5.2 demonstrated superior reasoning and problem-solving capabilities when tasked with security-centric prompts. This performance is particularly notable because the models were tested in a "prompt-only" environment, meaning the results reflect the model's internal training and logic rather than its ability to use external tools or search functions.
This trend suggests that the gap between the most expensive proprietary models and accessible open-weight models is narrowing rapidly. For the cyber security industry, this means that high-performance AI reasoning is becoming more decentralized, allowing organizations to potentially deploy powerful security analysis tools locally or within private clouds without relying on external API providers. The "Mythos at Home" reference in the report underscores this reality: the high-end performance once reserved for massive, closed systems is now available in models that can be hosted more flexibly.
Semgrep's Multimodal Security Ecosystem
Parallel to these benchmark findings, Semgrep has expanded its platform to leverage these AI advancements through "Semgrep Multimodal." This new strategy aims to solve one of the primary challenges in modern AppSec: the trade-off between the speed of rule-based detection and the depth of AI reasoning. By combining these two methodologies, Semgrep is positioning its platform to handle the entire lifecycle of a security vulnerability, from initial discovery to triage and final remediation.
The Semgrep ecosystem now includes a comprehensive suite of tools designed to secure the modern development pipeline:
- Semgrep Code (SAST): Focused on finding and fixing critical issues within the source code.
- Semgrep Supply Chain: Designed to identify vulnerabilities in open-source dependencies and actively block malware.
- Semgrep Secrets: Utilizing semantic analysis to locate and remediate hardcoded secrets.
- Semgrep Guardian: A specialized tool for scanning and fixing AI-generated code in real-time as it is written.
- Semgrep Workflows: Allowing organizations to build and deploy security pipelines that combine static analysis with AI at scale.
By integrating models like GLM 5.2 into this multimodal framework, Semgrep can provide more accurate detection with fewer false positives, as the AI reasoning component can validate the findings of traditional static analysis rules.
Industry Impact
The fact that an open-weight model can outperform a flagship proprietary model like Claude Opus 4.8 in a specialized field has profound implications for the AI and cyber security industries. First, it validates the investment in open-source and open-weight AI research, proving that community-driven or openly accessible models can reach the "state-of-the-art" threshold for technical tasks. This may lead to a shift in enterprise procurement, where security teams prioritize models that offer better data privacy and lower latency through local hosting without sacrificing performance.
Furthermore, the success of GLM 5.2 in cyber benchmarks may trigger a "specialization race." As general-purpose models like Claude and GPT continue to grow, specialized benchmarks like those provided by Semgrep will become the true testing ground for industry-specific utility. For AI developers, the focus may shift from general chat capabilities to fine-tuning models for specific high-value tasks like code auditing, vulnerability research, and automated remediation. This evolution will likely accelerate the adoption of AI in the software development life cycle (SDLC), as developers gain access to tools that are not only faster but also more accurate than previous generations of security software.
Frequently Asked Questions
Question: Which model did GLM 5.2 surpass in the Semgrep benchmarks?
Answer: GLM 5.2 outperformed Claude Opus 4.8, which is one of the leading proprietary models developed by Anthropic, specifically within Semgrep's cyber security testing framework.
Question: What does "open-weight" mean in the context of these results?
Answer: Open-weight refers to models where the trained parameters (weights) are made available to the public, allowing users to run the model on their own infrastructure. This is in contrast to proprietary models like Claude, which are typically accessed only via a restricted API.
Question: How does Semgrep Multimodal improve security detection?
Answer: Semgrep Multimodal combines the deterministic accuracy of rule-based detection (finding known patterns) with the probabilistic reasoning of AI (understanding context and intent). This combination allows for more effective triage and remediation of complex security issues that traditional tools might miss or misidentify.


