
Microsoft Research Unveils EvoLib: A Breakthrough Framework for LLMs to Learn and Evolve During Inference
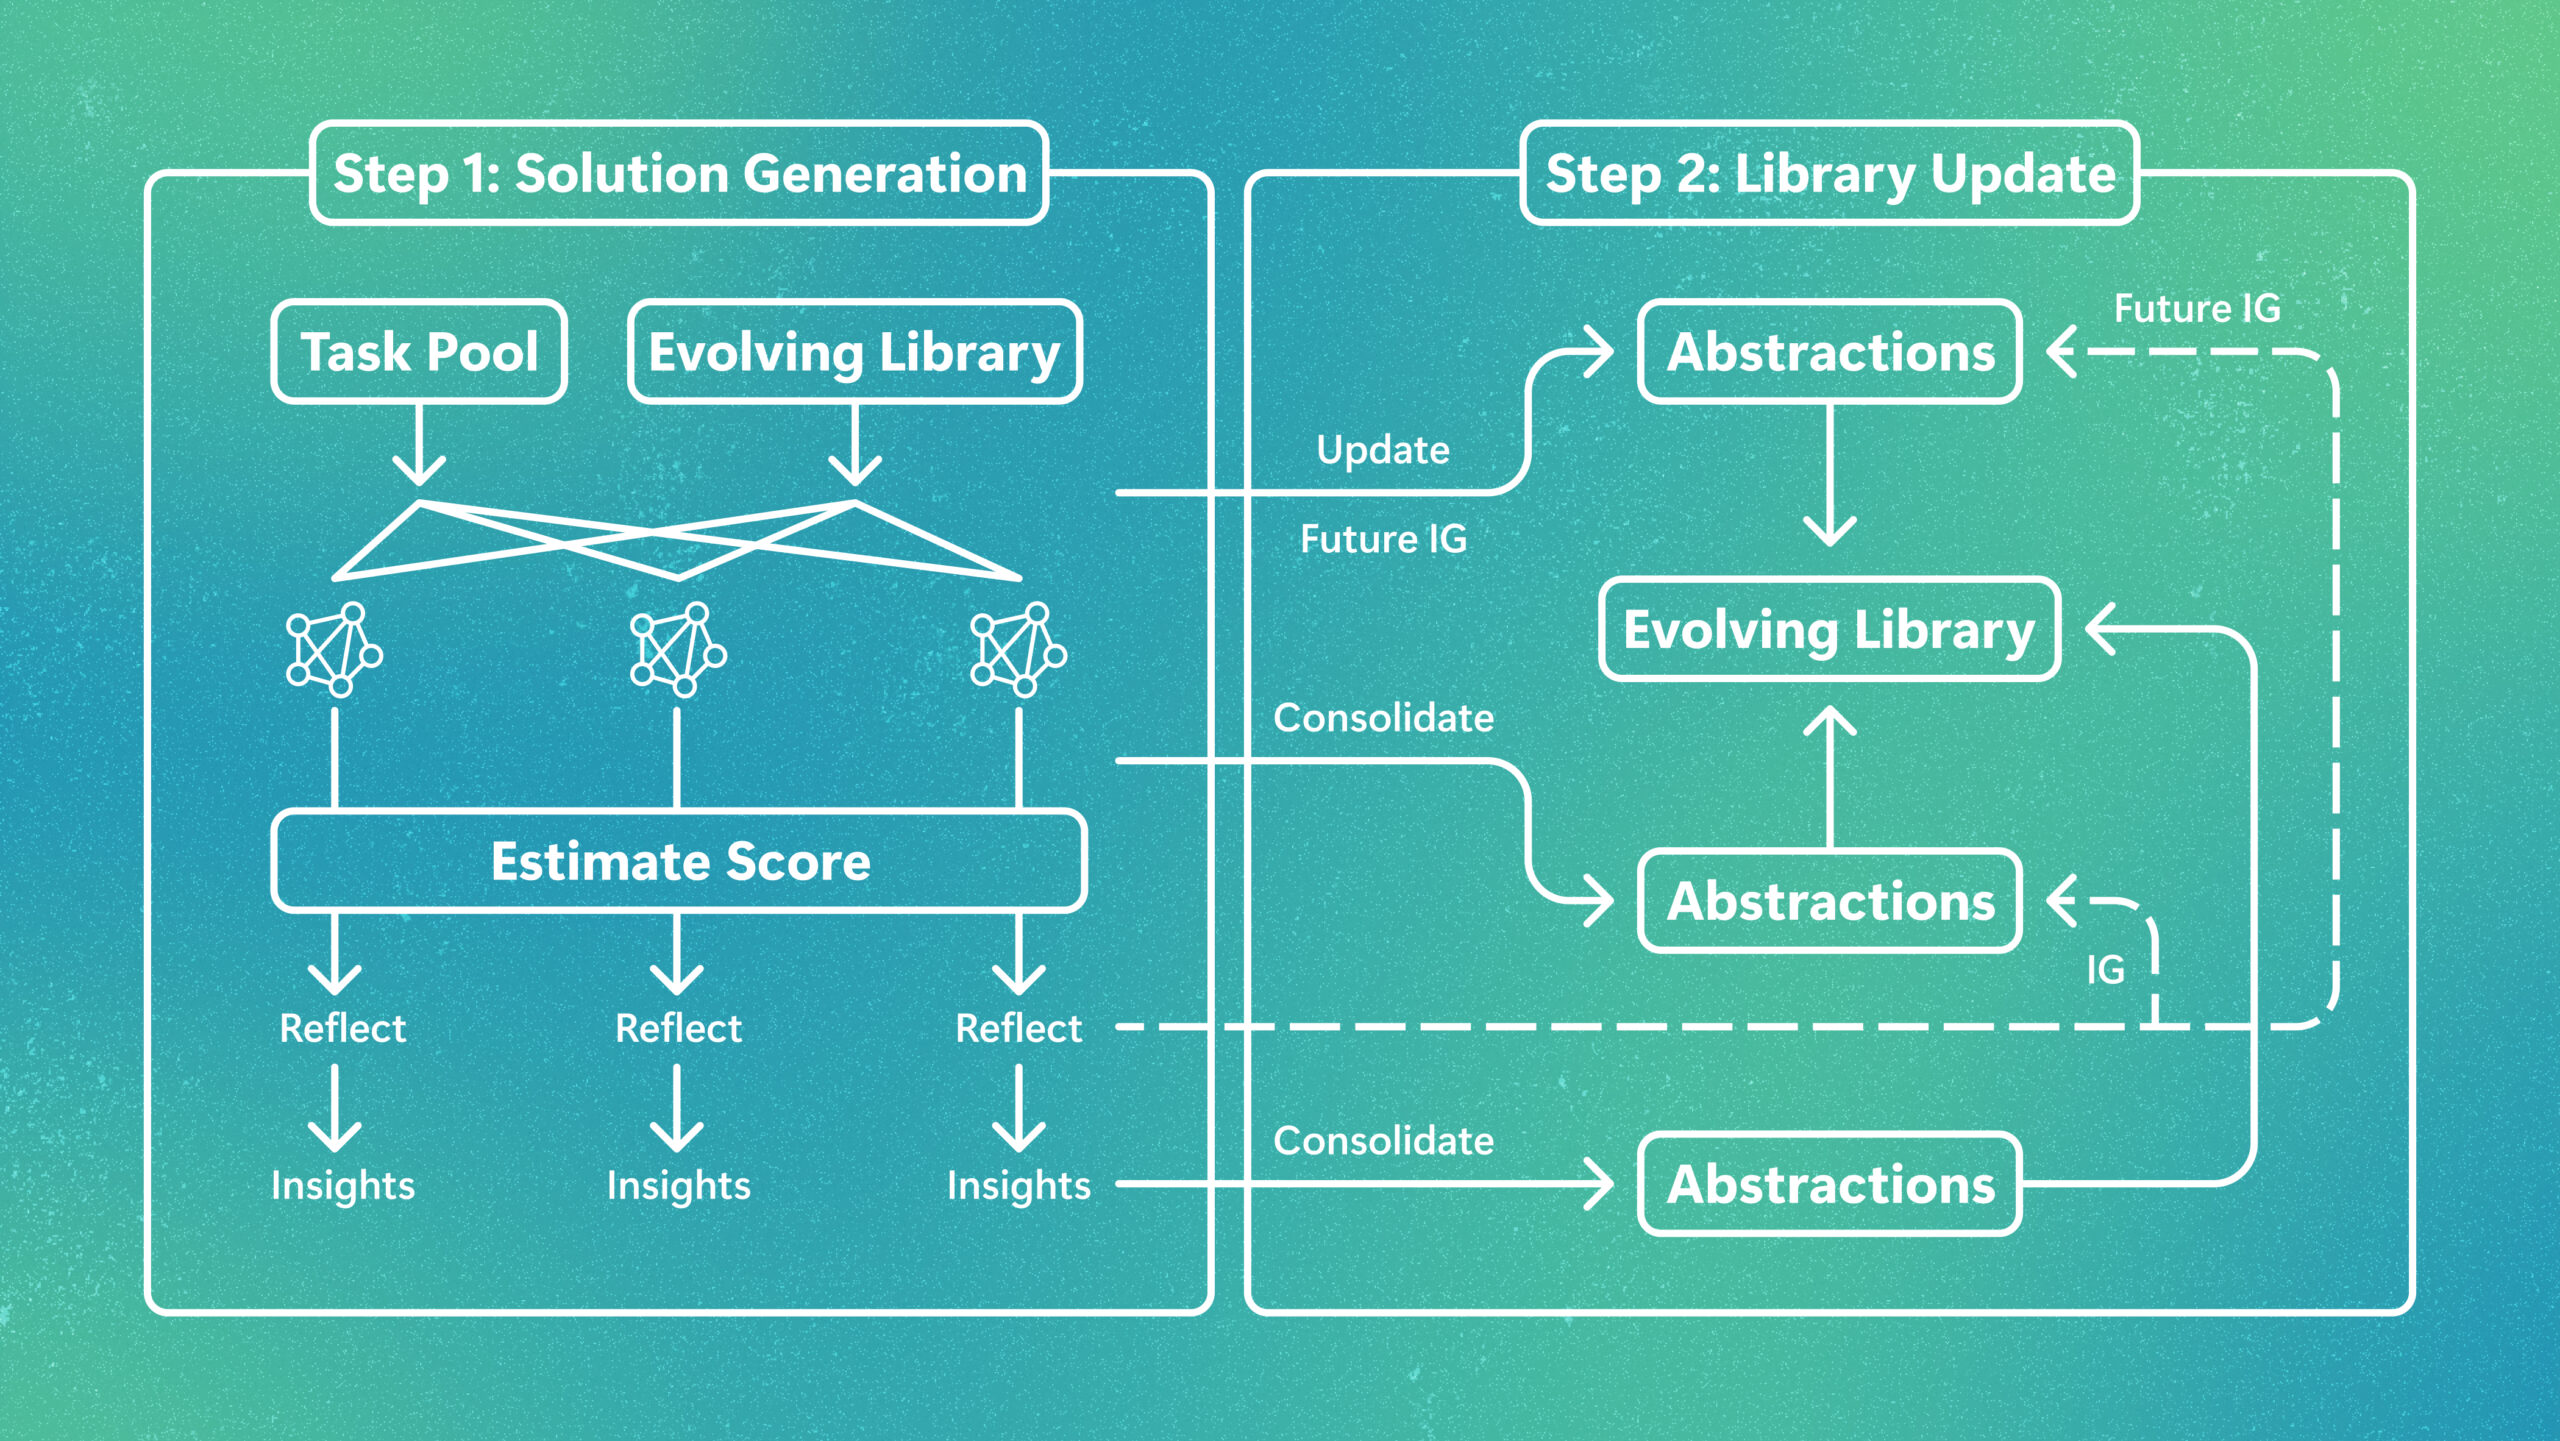
Microsoft Research has introduced EvoLib, a pioneering test-time learning framework designed to bridge the gap between static AI memory and true continuous learning. Unlike traditional methods that require costly parameter updates or fine-tuning, EvoLib enables large language models (LLMs) to accumulate, refine, and evolve knowledge directly during the inference process. By transforming raw experiences into a shared library of modular skills and reflective insights, the system allows AI agents to improve their performance on-the-fly. This self-supervised approach is particularly significant for 'black-box' models accessed via APIs, as it provides a way to enhance model intelligence without accessing internal weights. EvoLib represents a shift toward AI systems that grow more capable with every interaction, mirroring human-like learning patterns.
Key Takeaways
- Continuous Evolution Without Retraining: EvoLib allows LLMs to learn from their own inference trajectories and improve over time without requiring parameter updates or weight fine-tuning.
- Dual Knowledge Abstractions: The framework extracts two distinct types of knowledge: modular skills (reusable procedures) and reflective insights (rules distilled from past mistakes).
- Self-Supervised Optimization: It utilizes a dynamic weighting scheme based on Information Gain (IG) to prioritize the most useful knowledge for future tasks.
- Black-Box Compatibility: Because it operates at the inference level, EvoLib is fully compatible with proprietary models accessed through cloud APIs, such as those in Azure AI Foundry.
- Proven Performance Gains: Experimental results show significant improvements in mathematical reasoning, code generation, and complex multi-turn agentic workflows.
In-Depth Analysis
Beyond Static Memory: The Paradigm of Test-Time Learning
For years, the primary challenge for AI agents has been the distinction between 'memory' and 'learning.' While existing systems can store vast archives of past conversations or action histories, simply retrieving this data—often referred to as Retrieval-Augmented Generation (RAG)—does not constitute true learning. As these archives grow, identifying the most relevant information becomes increasingly difficult, and the model remains fundamentally static, unable to refine its strategies based on success or failure.
EvoLib, developed by a team at Microsoft Research including Weijia Xu and Jianfeng Gao, introduces a 'test-time learning' paradigm. Instead of treating past experiences as a static database, EvoLib treats them as raw material for knowledge synthesis. It enables a model to observe its own reasoning paths during inference and extract high-level abstractions. This means the AI doesn't just remember what it did; it understands why a certain approach worked or why a mistake occurred, allowing it to adapt its behavior for the next task. This mimics the human ability to form heuristics and strategies from experience, moving beyond rote memorization toward genuine cognitive evolution.
The Dual-Engine Architecture: Modular Skills and Reflective Insights
At the core of EvoLib is a shared, evolving library that categorizes knowledge into two primary forms: modular skills and reflective insights. Modular skills are defined as reusable procedures or functions. For instance, in a coding task, a modular skill might be a specific sub-routine for data validation that the model 'discovered' was effective. In an agentic workflow, it could be a standardized sequence for handling customer support tickets. These skills are not just text snippets but functional building blocks that can be re-applied across different problem instances.
Reflective insights, on the other hand, are natural-language rules distilled from the model’s own errors. When a model fails a task, EvoLib’s self-supervised mechanism analyzes the failure and generates a 'lesson learned.' These insights act as guardrails, preventing the model from repeating the same mistakes in future iterations. To ensure the library remains manageable and high-quality, EvoLib employs a principled weighting and consolidation mechanism. Using metrics like Information Gain (IG) and Future Information Gain, the system evaluates which pieces of knowledge are most likely to improve future performance. Low-utility entries are pruned or consolidated, while highly effective strategies are promoted, ensuring the library evolves from instance-specific observations into increasingly general and robust knowledge.
Black-Box Compatibility and the Future of AI Deployment
One of the most significant aspects of EvoLib is its compatibility with 'black-box' models. Most advanced learning techniques in AI require access to the model's internal weights (gradients) to perform updates. However, many of the world's most powerful LLMs are only accessible via APIs, where the internal parameters are hidden. EvoLib bypasses this limitation by operating entirely at the prompt and inference level.
This architecture has profound implications for enterprise AI. Organizations using services like Azure AI Foundry can implement EvoLib to create agents that grow smarter within their specific corporate context—learning the nuances of internal PowerShell remediation or specific code review standards—without the massive computational overhead and privacy risks associated with fine-tuning. By maintaining the learning logic outside the model itself, EvoLib provides a scalable design pattern that sits between stateless prompting and full-scale retraining, offering a more sustainable path for long-term AI deployment.
Industry Impact
- Efficiency in Agentic Workflows: By reducing the need for repetitive prompting and manual error correction, EvoLib significantly lowers the operational cost and increases the reliability of AI agents in production environments.
- Democratization of AI Optimization: Smaller organizations that lack the resources for large-scale model training can now achieve performance improvements through inference-time learning, leveling the playing field in AI capabilities.
- Shift in AI Development Focus: The industry may see a shift from focusing solely on 'bigger models' to 'smarter systems' that emphasize the architecture of knowledge management and test-time adaptation.
- Enhanced Security and Governance: Since EvoLib uses a modular library, it offers better auditability than traditional fine-tuning. Flawed 'skills' can be identified, rolled back, or edited without needing to retrain the entire underlying model.
Frequently Asked Questions
Question: Does EvoLib require human feedback to learn?
No, EvoLib is designed to be self-supervised. It learns from the model's own inference trajectories and internal reasoning, meaning it can identify successful patterns and mistakes without requiring ground-truth labels or constant human intervention.
Question: Is EvoLib compatible with any LLM?
Yes, EvoLib is built for today's AI landscape. Because it does not require access to model weights or parameter updates, it can be applied to any black-box language model or AI system deployed through standard APIs.
Question: How does EvoLib prevent the knowledge library from becoming too large?
EvoLib uses a dynamic weighting and consolidation scheme based on Information Gain. It continually evaluates the utility of each skill and insight, refining or removing entries that do not contribute to improved performance, which keeps the library efficient and focused.
