How to Build a Simple AI Web Scraper with Python for Efficient LLM-Powered QA Engines
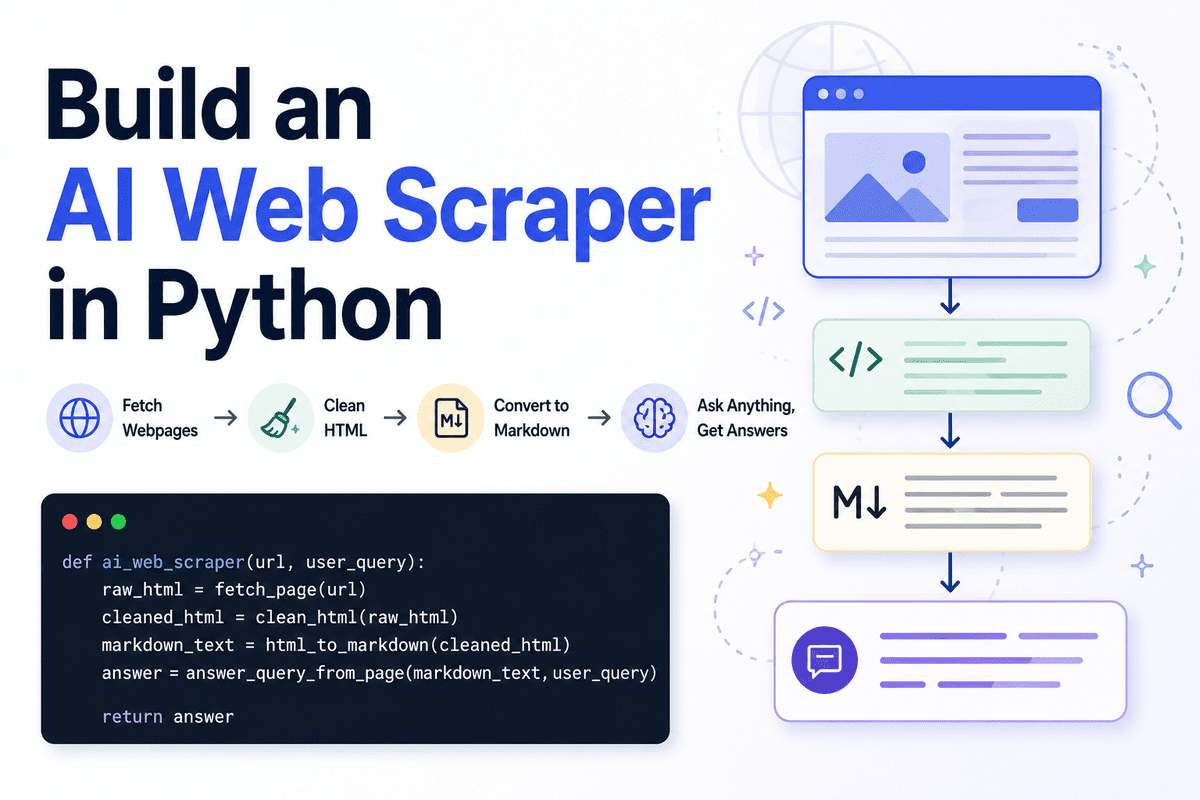
This technical guide, authored by Abid Ali Awan for KDnuggets, outlines a streamlined approach to building an AI-powered web scraper using Python. The methodology focuses on transforming raw webpages into efficient, lightweight Question-and-Answer (QA) engines. By implementing a pipeline that cleans HTML and converts content into Markdown, the process ensures that Large Language Models (LLMs) receive structured, relevant data. This optimization is critical for reducing token usage and improving the accuracy of the AI's responses. The article provides a conceptual framework for developers to move beyond traditional scraping toward intelligent data extraction that prioritizes focused answers and cost-effective model interaction, making it a vital resource for those integrating real-time web data into AI applications.
Key Takeaways
- Python-Based Integration: The system utilizes Python to bridge the gap between raw web data and Large Language Models.
- HTML Preprocessing: Cleaning HTML and converting it to Markdown is essential for removing noise and preserving content structure.
- Token Efficiency: Reducing the volume of data sent to the LLM lowers costs and improves processing speed by minimizing token consumption.
- QA Engine Transformation: The primary goal is to turn any webpage into a functional, lightweight QA engine that provides focused answers.
In-Depth Analysis
The Importance of HTML Cleaning and Markdown Conversion
In the development of an AI-powered web scraper, the transition from raw HTML to a structured format like Markdown is a critical preprocessing step. Raw HTML is often cluttered with scripts, styles, and nested tags that do not contribute to the actual informational content of a page. For an LLM, this 'noise' can lead to confusion and decreased accuracy. By cleaning the HTML, developers can isolate the core text and relevant metadata.
Converting this cleaned data into Markdown further enhances the model's ability to parse information. Markdown retains the semantic structure of the original content—such as headers, lists, and links—without the heavy overhead of HTML syntax. This structural preservation allows the LLM to understand the hierarchy and context of the information, which is vital for generating accurate and context-aware answers in a QA setting. This transformation is the foundation of turning a static webpage into a dynamic, queryable data source.
Optimizing LLM Performance through Token Reduction
One of the most significant challenges in building AI applications is managing token usage. Large Language Models charge based on the number of tokens processed, and they also have strict context window limits. A standard webpage, if fed directly into an LLM, could easily consume thousands of tokens, much of which would be wasted on non-essential formatting or boilerplate text.
By focusing on 'lightweight' data extraction, the Python-based scraper described by Abid Ali Awan addresses this efficiency gap. The process of cleaning and converting content ensures that only the most relevant information is passed to the model. This reduction in token usage has a twofold benefit: it significantly lowers the operational costs of the AI engine and allows the model to focus its 'attention' on the actual data, leading to more precise and focused answers. Efficiency in data preparation directly correlates to the performance and scalability of the resulting QA engine.
Building a Lightweight QA Engine Architecture
The ultimate objective of this scraping methodology is the creation of a QA engine. Unlike traditional scrapers that simply store data in a database, an AI-powered scraper enables real-time interaction with the web content. By integrating the cleaned Markdown content with an LLM, the system can interpret user queries and extract specific answers from the scraped data.
This architecture represents a shift toward 'on-the-fly' knowledge retrieval. Because the engine is lightweight, it can be deployed across various platforms without requiring massive computational resources. The focus remains on returning concise, relevant answers rather than dumping large amounts of text. This makes the tool particularly useful for applications requiring quick insights from specific web sources, such as research tools, monitoring systems, or automated customer support bots that rely on external documentation.
Industry Impact
The methodology of building simple, AI-driven scrapers has profound implications for the AI industry, particularly in the realm of Retrieval-Augmented Generation (RAG). As companies look for ways to make LLMs more useful by grounding them in real-time data, the ability to efficiently ingest web content becomes paramount. By prioritizing token reduction and data cleanliness, this approach sets a standard for cost-effective AI development. It lowers the barrier to entry for developers to create specialized AI tools that can interact with the vast amount of information available on the open web, potentially leading to a surge in niche, high-accuracy QA applications across various sectors.
Frequently Asked Questions
Question: Why is Markdown preferred over raw HTML for AI scraping?
Markdown is preferred because it is much more token-efficient than HTML while still preserving the essential structure of the document (like headings and lists). This helps the LLM understand the context of the information without being distracted by the complex syntax and 'noise' found in raw HTML code.
Question: How does this method reduce the cost of using Large Language Models?
This method reduces costs by cleaning the data and removing unnecessary elements before it is sent to the LLM. Since LLM providers typically charge per token, sending a smaller, more focused amount of text (Markdown) instead of a full HTML page significantly lowers the number of tokens used per query.
Question: Can this approach be used for any webpage?
Yes, the methodology of cleaning HTML and converting it to Markdown is designed to be versatile. It can be applied to any webpage to transform it into a lightweight source of information for an AI-powered QA engine, provided the scraper can access the page's content.