
NanoGPT Speedrun Frontier: Fable 5 and Opus 5 Lead the Race in Closing the Human Performance Gap
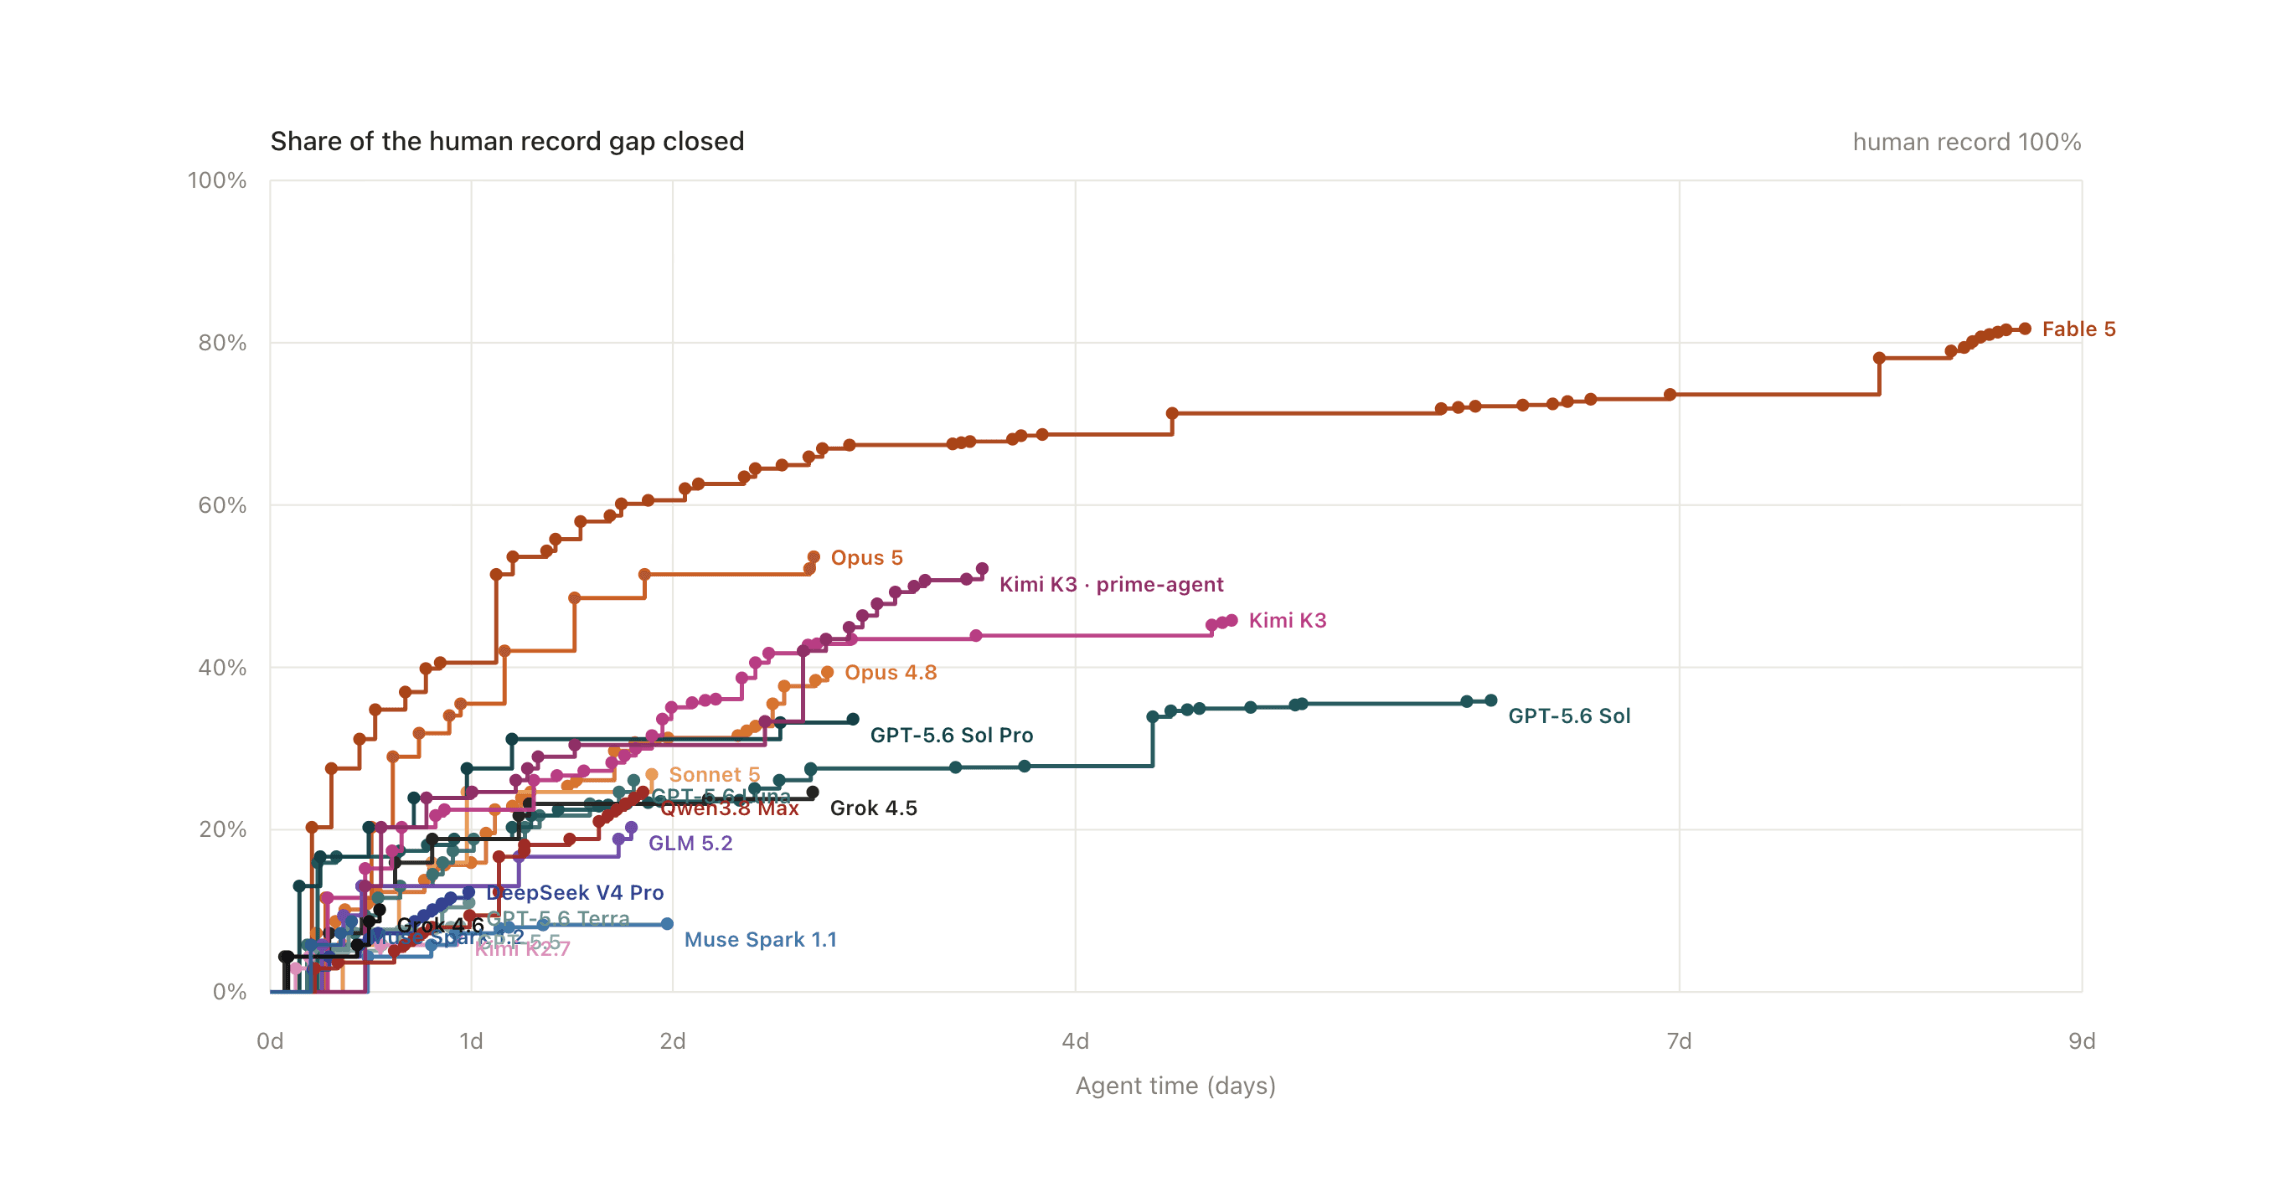
The NanoGPT Speedrun Frontier leaderboard, released by Prime Intellect, showcases the rapid advancement of AI agents in optimizing model training. Fable 5 currently dominates the field, having closed 81.7% of the human record gap over an 8.7-day period using the claude-code agent. Other significant contenders include Opus 5 and Kimi K3, which have closed 53.6% and 52.2% of the gap, respectively. The data highlights a diverse ecosystem of agents, including prime-agent, codex, and grok-cli, operating across various models like GPT-5.6, Grok 4.5, and DeepSeek V4 Pro. This benchmark serves as a critical indicator of how close autonomous AI systems are coming to matching or exceeding human-level expertise in complex optimization tasks.
Key Takeaways
- Fable 5 Leads the Frontier: Fable 5 has achieved the highest progress to date, closing 81.7% of the human record gap with a validated result of 2,726.
- High Efficiency from Opus and Kimi: Opus 5 and Kimi K3 have both surpassed the 50% mark, closing 53.6% and 52.2% of the gap in 2.9 and 3.6 days, respectively.
- Diverse Agent Ecosystem: The speedrun utilizes a variety of specialized agents such as claude-code, prime-agent, kimi-code, and codex, with configurations ranging from 'high' to 'max' at 24-hour intervals.
- Rapid Iteration Cycles: Models like Sonnet 5 and GPT-5.6 Luna show high efficiency, closing over 26% of the gap in approximately 2 days of agent time.
In-Depth Analysis
The Dominance of Fable 5 and the Human Record Gap
The NanoGPT Speedrun Frontier represents a competitive benchmark where AI agents attempt to close the performance gap between standard training and the human record. Fable 5 stands out as the current leader, achieving an 81.7% closure of this gap. This result was obtained using the 'claude-code' agent with a 'high' setting over a duration of 8.7 days. The validated result of 2,726 for Fable 5 is significantly ahead of its closest competitors, marking a major milestone in autonomous optimization. The trajectory for Fable 5 indicates a sustained effort over a longer 'Agent time' compared to other models, suggesting that extended compute and iteration time are currently necessary to reach the upper echelons of human-level performance.
Comparative Performance in the Serial Era
Several models are categorized under the 'serial era,' indicating a specific phase or methodology in the speedrun. Opus 5 and Kimi K3 are the frontrunners in this category. Opus 5 closed 53.6% of the gap in just 2.9 days, while Kimi K3 followed closely with 52.2% in 3.6 days. Interestingly, Kimi K3 appears twice in the top rankings; once using the 'prime-agent' (52.2% closed) and once using 'kimi-code' (45.8% closed). This highlights the impact of the agent software itself on the model's performance. While the underlying model remains the same, the choice of agent and its configuration (e.g., 'max @24H') can result in a nearly 7% difference in gap closure.
Efficiency and Agent Trajectories
When analyzing the 'Agent time' metric, some models demonstrate remarkable efficiency. Sonnet 5, for instance, closed 26.8% of the gap in only 2.0 days. Similarly, GPT-5.6 Luna closed 26.1% in 1.9 days. These results suggest that while they haven't reached the total progress of Fable 5, their rate of improvement per day is highly competitive. The leaderboard also tracks 'running' models such as Qwen3.8 Max, DeepSeek V4 Pro, and Grok 4.6, which are currently at 24.6%, 12.3%, and 10.1% gap closure respectively. The data for DeepSeek V4 Pro shows it reached 12.3% in just 1.1 days, indicating a potentially steep upward trajectory as more agent time is applied.
Industry Impact
The NanoGPT Speedrun Frontier is a significant development for the AI industry as it moves beyond static benchmarks toward dynamic, task-oriented optimization. By measuring the 'Share of the human record gap closed,' Prime Intellect provides a clear metric for how autonomous agents are evolving to handle complex engineering and coding tasks. The involvement of major model families—including GPT-5.6, Grok, Kimi, and DeepSeek—underscores the global nature of this competition. As agents like claude-code and prime-agent continue to iterate, the industry is likely to see a shift where AI models are not just used for generation, but for the autonomous improvement of other AI systems, potentially leading to a self-reinforcing cycle of optimization.
Frequently Asked Questions
Question: What is the primary metric used in the NanoGPT Speedrun Frontier?
The primary metric is the "Share of the human record gap closed," which measures how much of the performance difference between a baseline and the human record has been eliminated by the AI agent.
Question: Which AI agent is currently the most successful in this benchmark?
Based on the current leaderboard, the 'claude-code' agent, when paired with the Fable 5 model, is the most successful, having closed 81.7% of the human record gap.
Question: How does agent time affect the results?
Agent time, measured in days, represents the duration the AI agent spent on the task. While more time generally leads to higher gap closure (as seen with Fable 5's 8.7 days), some models like Sonnet 5 and GPT-5.6 Luna show significant progress in a much shorter timeframe (around 2 days).
