
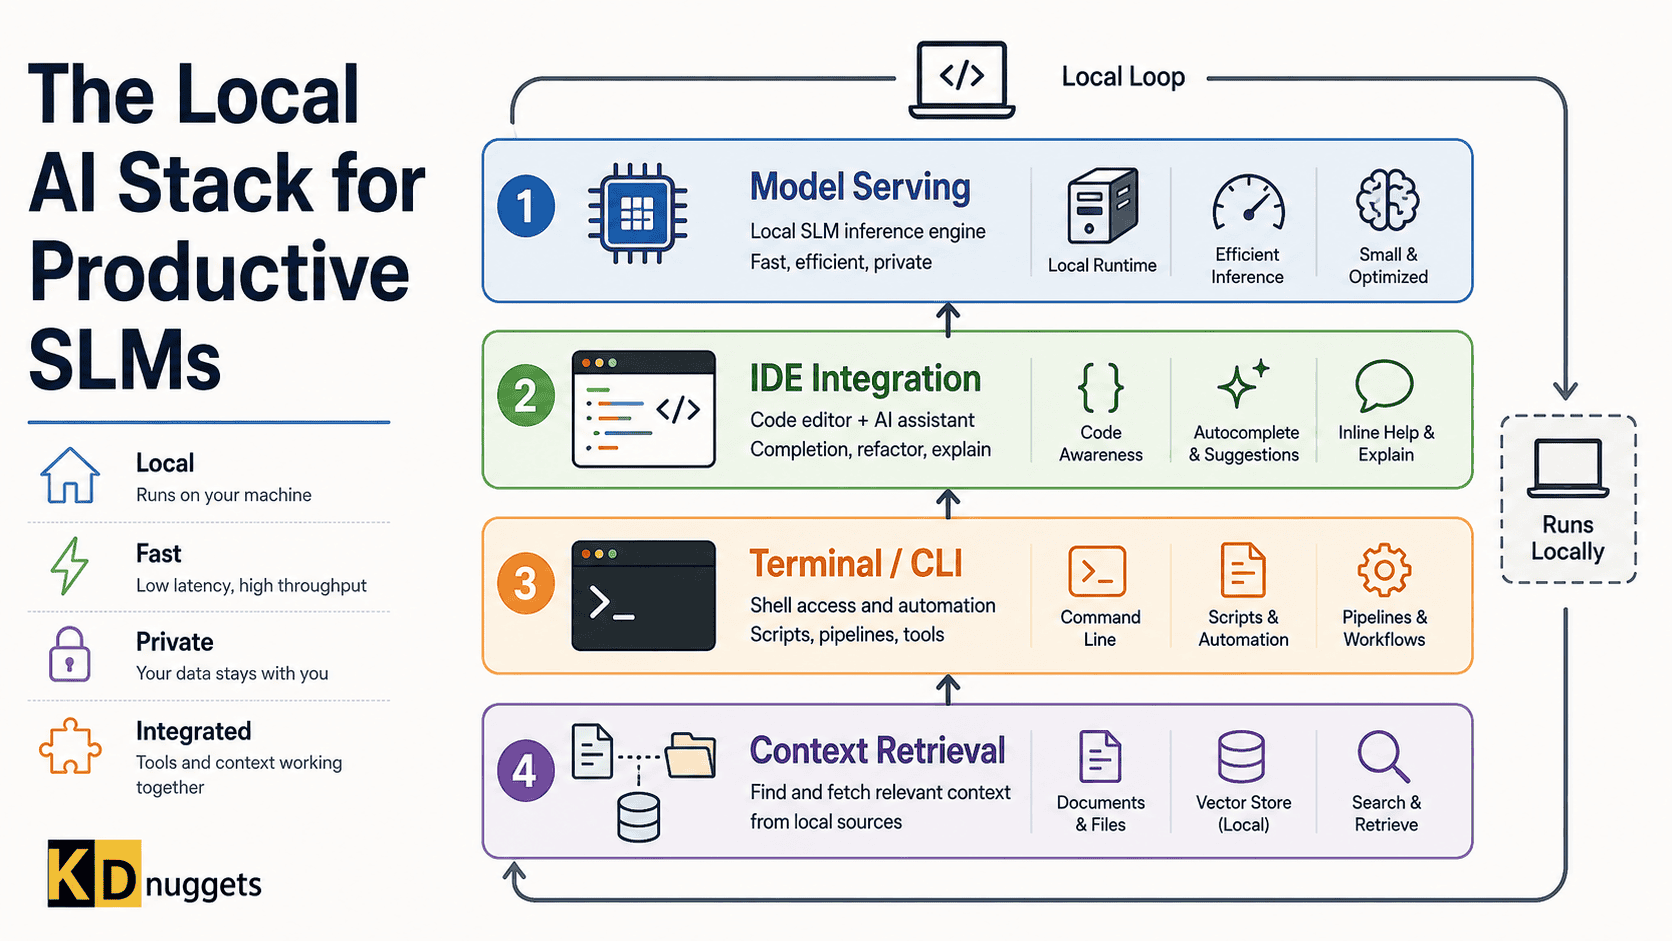
The Local AI Stack for Productive SLMs: A Practical Framework for Model Serving and Context Retrieval
This article examines a practical framework designed for selecting the appropriate tools within a local AI stack, specifically optimized for Small Language Models (SLMs). Authored by Vinod Chugani and featured on KDnuggets, the framework addresses the complexities of local AI deployment by breaking down the setup into functional layers. The analysis focuses on the two primary pillars of this stack: model serving and context retrieval. By providing a structured approach to tool selection, the framework aims to enhance productivity for developers and organizations looking to leverage the power of SLMs within a localized environment, ensuring efficient performance and streamlined workflows.
Key Takeaways
- Structured Tool Selection: The framework provides a practical guide for choosing the right tools at every layer of a local AI setup.
- Focus on SLMs: The stack is specifically designed to maximize the productivity and efficiency of Small Language Models (SLMs).
- Core Components: Model serving and context retrieval are identified as the critical layers for a functional local AI environment.
- Productivity Optimization: The primary goal of the framework is to streamline the local AI workflow to improve overall developer output.
In-Depth Analysis
The Architecture of a Local AI Stack
The concept of a "Local AI Stack" represents a significant shift in how artificial intelligence is deployed and utilized. Unlike cloud-based solutions, a local stack requires a carefully orchestrated selection of tools that can operate within the resource constraints of local hardware. The framework proposed by Vinod Chugani emphasizes a layered approach, suggesting that a successful deployment is not about a single piece of software, but rather the integration of multiple specialized tools. This modularity allows for greater flexibility, enabling developers to swap components as new technologies emerge or as specific project requirements change. By focusing on a "practical framework," the author highlights the need for a systematic method to evaluate these tools, ensuring that each layer—from the base infrastructure to the application interface—is optimized for the intended use case.
Optimizing for Small Language Models (SLMs)
Small Language Models (SLMs) have gained prominence as efficient alternatives to their larger counterparts, particularly for local applications where computational power and memory may be limited. The framework specifically targets "productive SLMs," implying that the goal is not just to run these models, but to do so in a way that yields meaningful results and high performance. The choice of tools within the stack must therefore account for the unique characteristics of SLMs, such as their lower latency and reduced resource requirements. By tailoring the stack to these models, the framework ensures that the local environment can support sophisticated AI tasks without the overhead typically associated with massive, cloud-scale architectures. This focus on productivity suggests that the framework is designed for real-world application, where speed and reliability are paramount.
Critical Layers: Model Serving and Context Retrieval
At the heart of the local AI stack are two essential layers: model serving and context retrieval. Model serving refers to the mechanism by which the SLM is hosted and made accessible to other applications. This layer is responsible for managing the model's lifecycle, handling requests, and ensuring that the model performs efficiently on the local CPU or GPU. Without an effective serving layer, even the most capable SLM cannot be utilized productively.
Parallel to serving is the context retrieval layer. In a local AI setup, context retrieval is the process of identifying and providing the model with the specific information it needs to complete a task accurately. This often involves searching through local datasets or documents to find relevant snippets that the model can use as a reference. The framework identifies this as a distinct layer, highlighting its importance in the overall stack. By optimizing context retrieval, developers can significantly improve the accuracy and relevance of the SLM's outputs, making the entire local AI system more effective for complex, data-driven tasks.
Industry Impact
The introduction of a structured framework for local AI stacks has several implications for the broader AI industry. First, it democratizes access to advanced AI capabilities by providing a roadmap for local deployment, reducing the dependency on expensive and often privacy-invasive cloud services. Second, the emphasis on SLMs reflects a growing industry trend toward "right-sized" AI, where the focus shifts from model size to task-specific efficiency. This approach is particularly relevant for sectors with strict data sovereignty requirements, such as healthcare or finance, where local processing is a necessity. Finally, by formalizing the layers of the AI stack, this framework encourages the development of more specialized and interoperable tools, potentially leading to a more robust and diverse ecosystem of local AI technologies.
Frequently Asked Questions
Question: What is the purpose of the local AI stack framework?
The framework is designed to help developers choose the right tools for each layer of a local AI setup, ensuring that Small Language Models (SLMs) can be deployed and used productively on local hardware.
Question: What are the most important layers mentioned in the framework?
The framework specifically highlights model serving and context retrieval as critical layers. Model serving handles the execution of the AI model, while context retrieval ensures the model has access to the necessary data to perform its tasks.
Question: Why is the focus on Small Language Models (SLMs) instead of larger models?
SLMs are better suited for local deployment because they require fewer computational resources and offer lower latency, making them ideal for productive, real-world applications on local machines where hardware constraints are a factor.
